
SoMarkAI / OXR
A 1.3B-parameter document parsing model that converts PDFs and document images into Markdown or JSON with layout coordinates.
description README.md
SoMark|OXR
An open-source document parsing model with SOTA accuracy and speed, using an RSI loop during post-training.
Turn documents into Agent-Friendly data.
🌐 Online Demo | 🔥 🆓 Free API | ❓ FAQ

English · 简体中文
OXR (Optical Everything Recognition) is an open-source model from the SoMark team. It turns PDFs and document images into Agent-Friendly data in Markdown or JSON, with layout coordinates included.
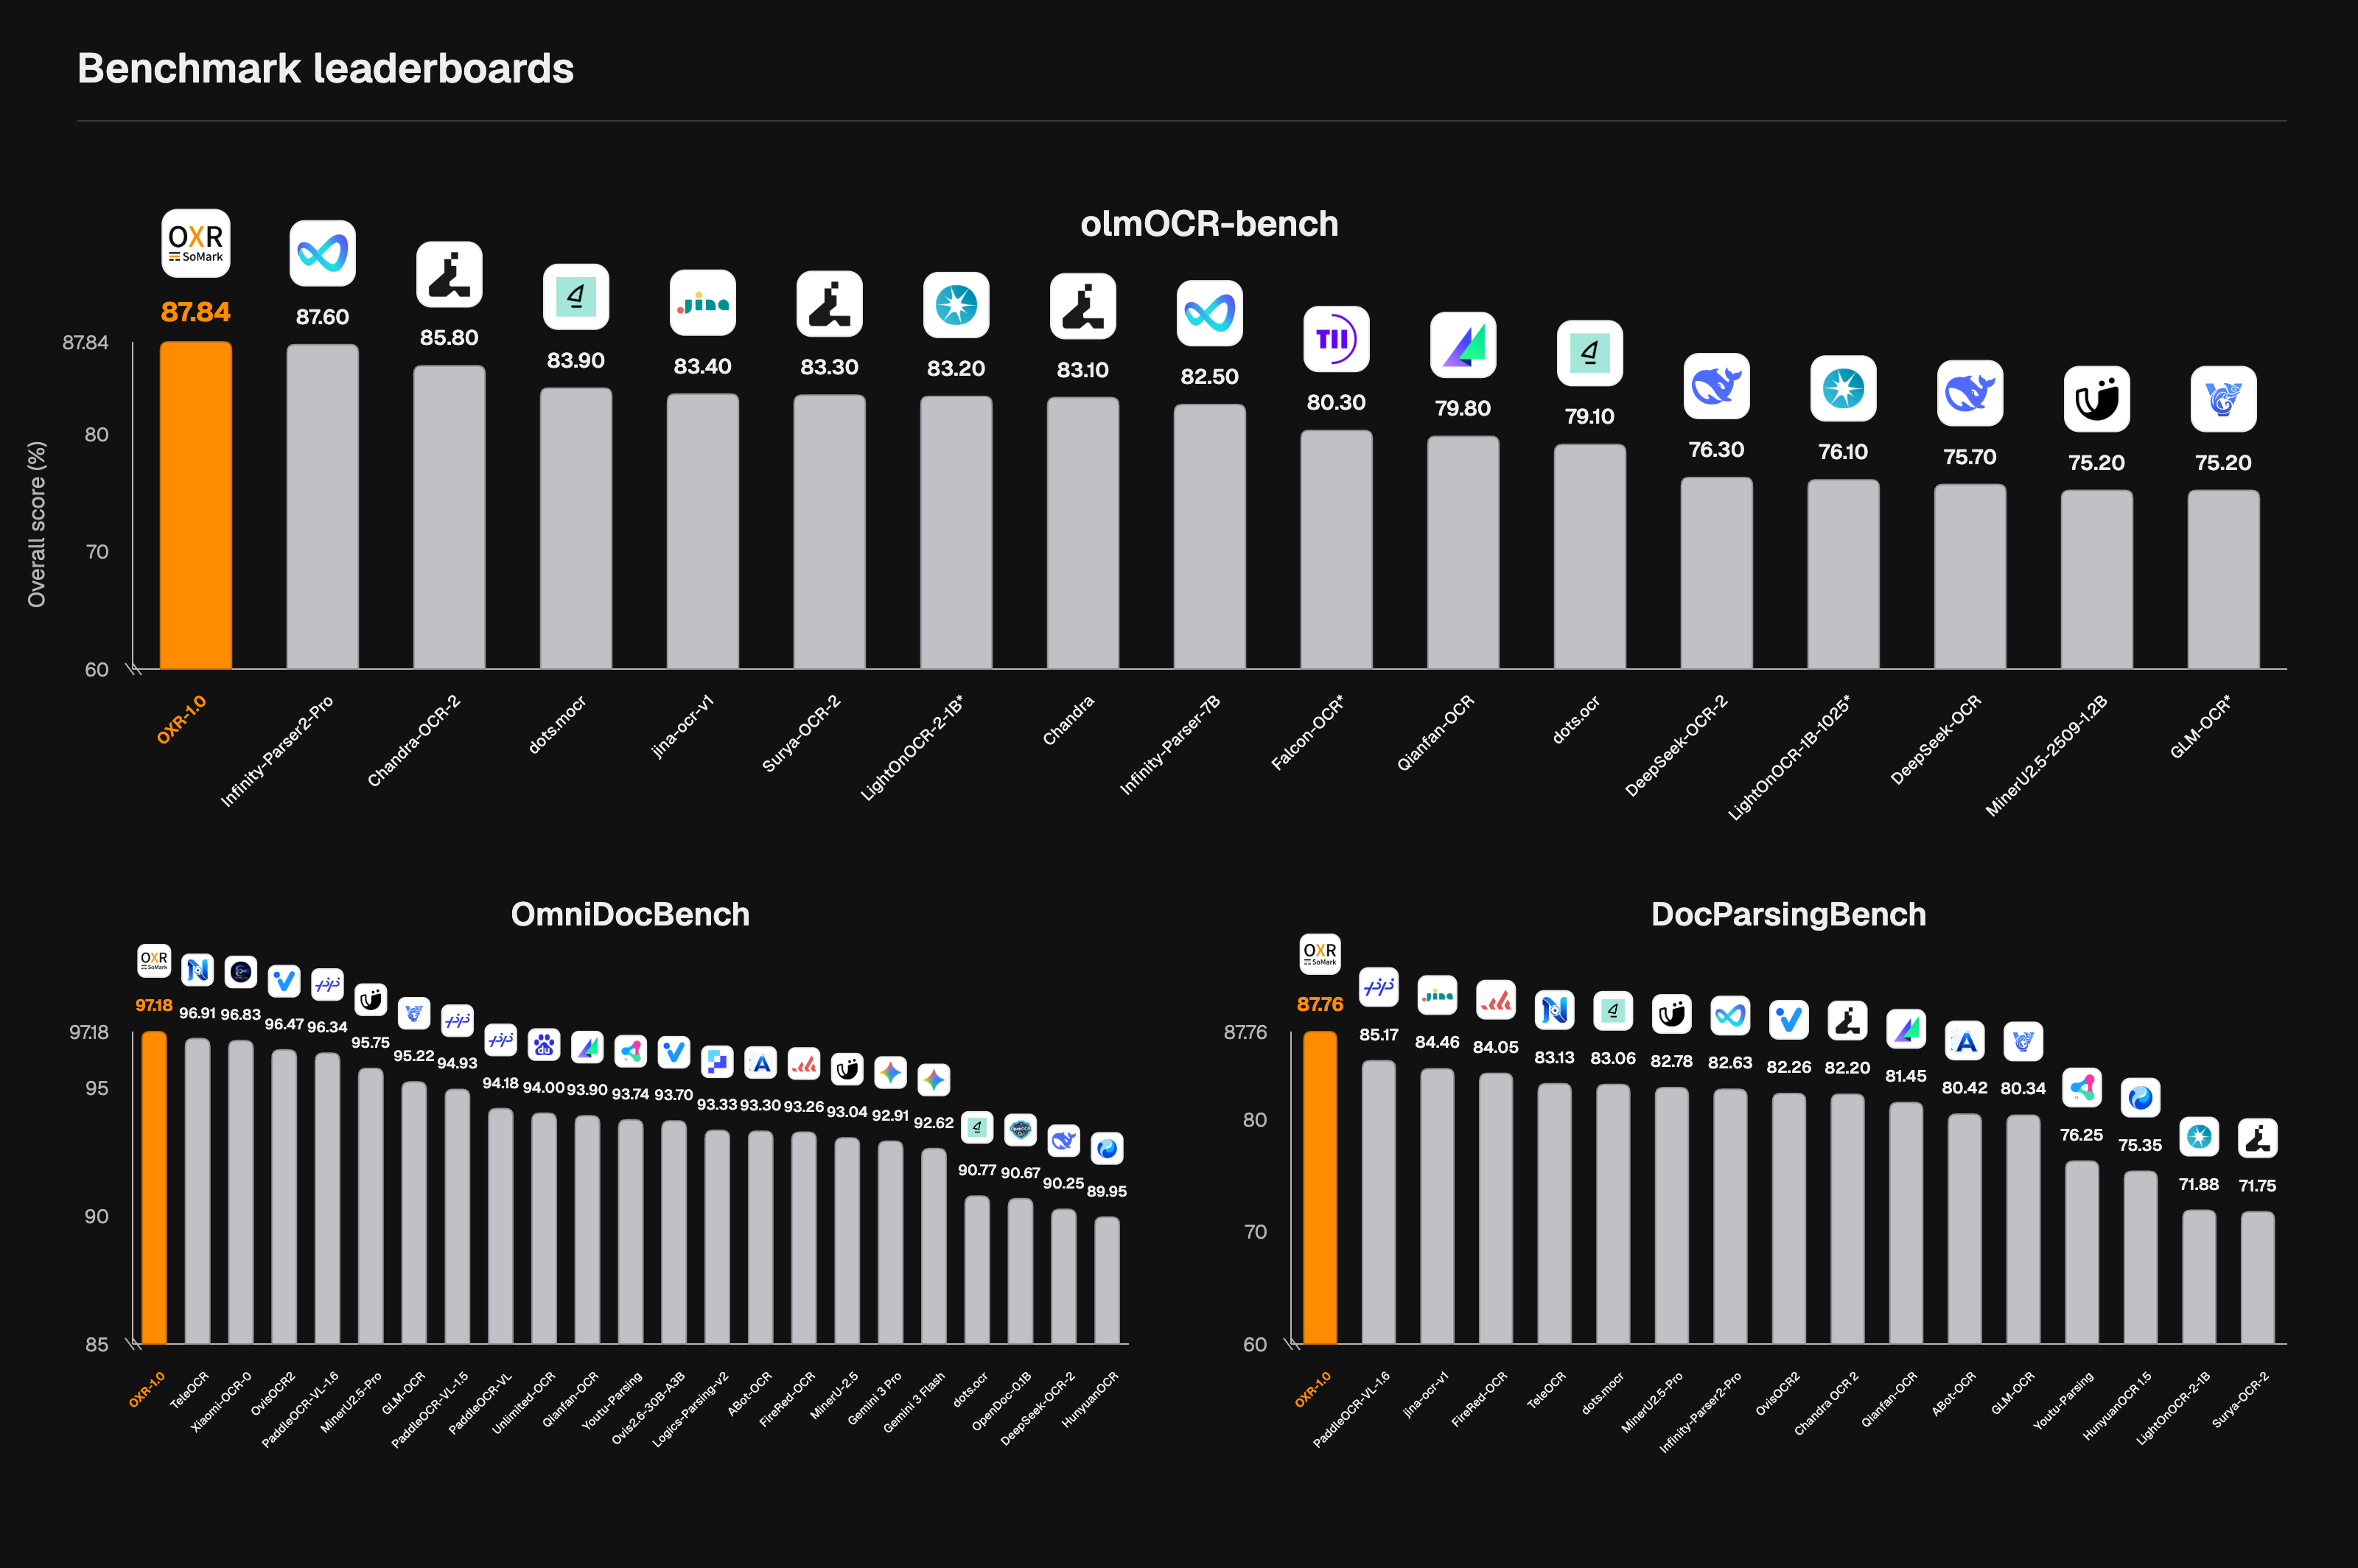
Pretrained from scratch, OXR uses a recursive self-improvement (RSI) loop during post-training—a first in document parsing. With just 1.3B parameters, OXR ranks #1 on olmOCR-Bench, OmniDocBench, and DocParsingBench while delivering industry-leading parsing speed.
OXR is the first to make its layout analysis module independent and pluggable. This design accelerates parsing and supports replacing the built-in layout model with a custom one. OXR continues to handle content recognition and reading order, enabling adaptation across diverse scenarios with minimal integration effort.
If this project helps you, please click ⭐ Star in the top-right corner to support us. It's the best encouragement you can give the developers!
Why OXR?
-
🎯 SOTA Accuracy. #1 Across Three Benchmarks.
- OXR ranks 🏆#1 on olmOCR-Bench, OmniDocBench, and DocParsingBench, with a particularly wide lead in table parsing.
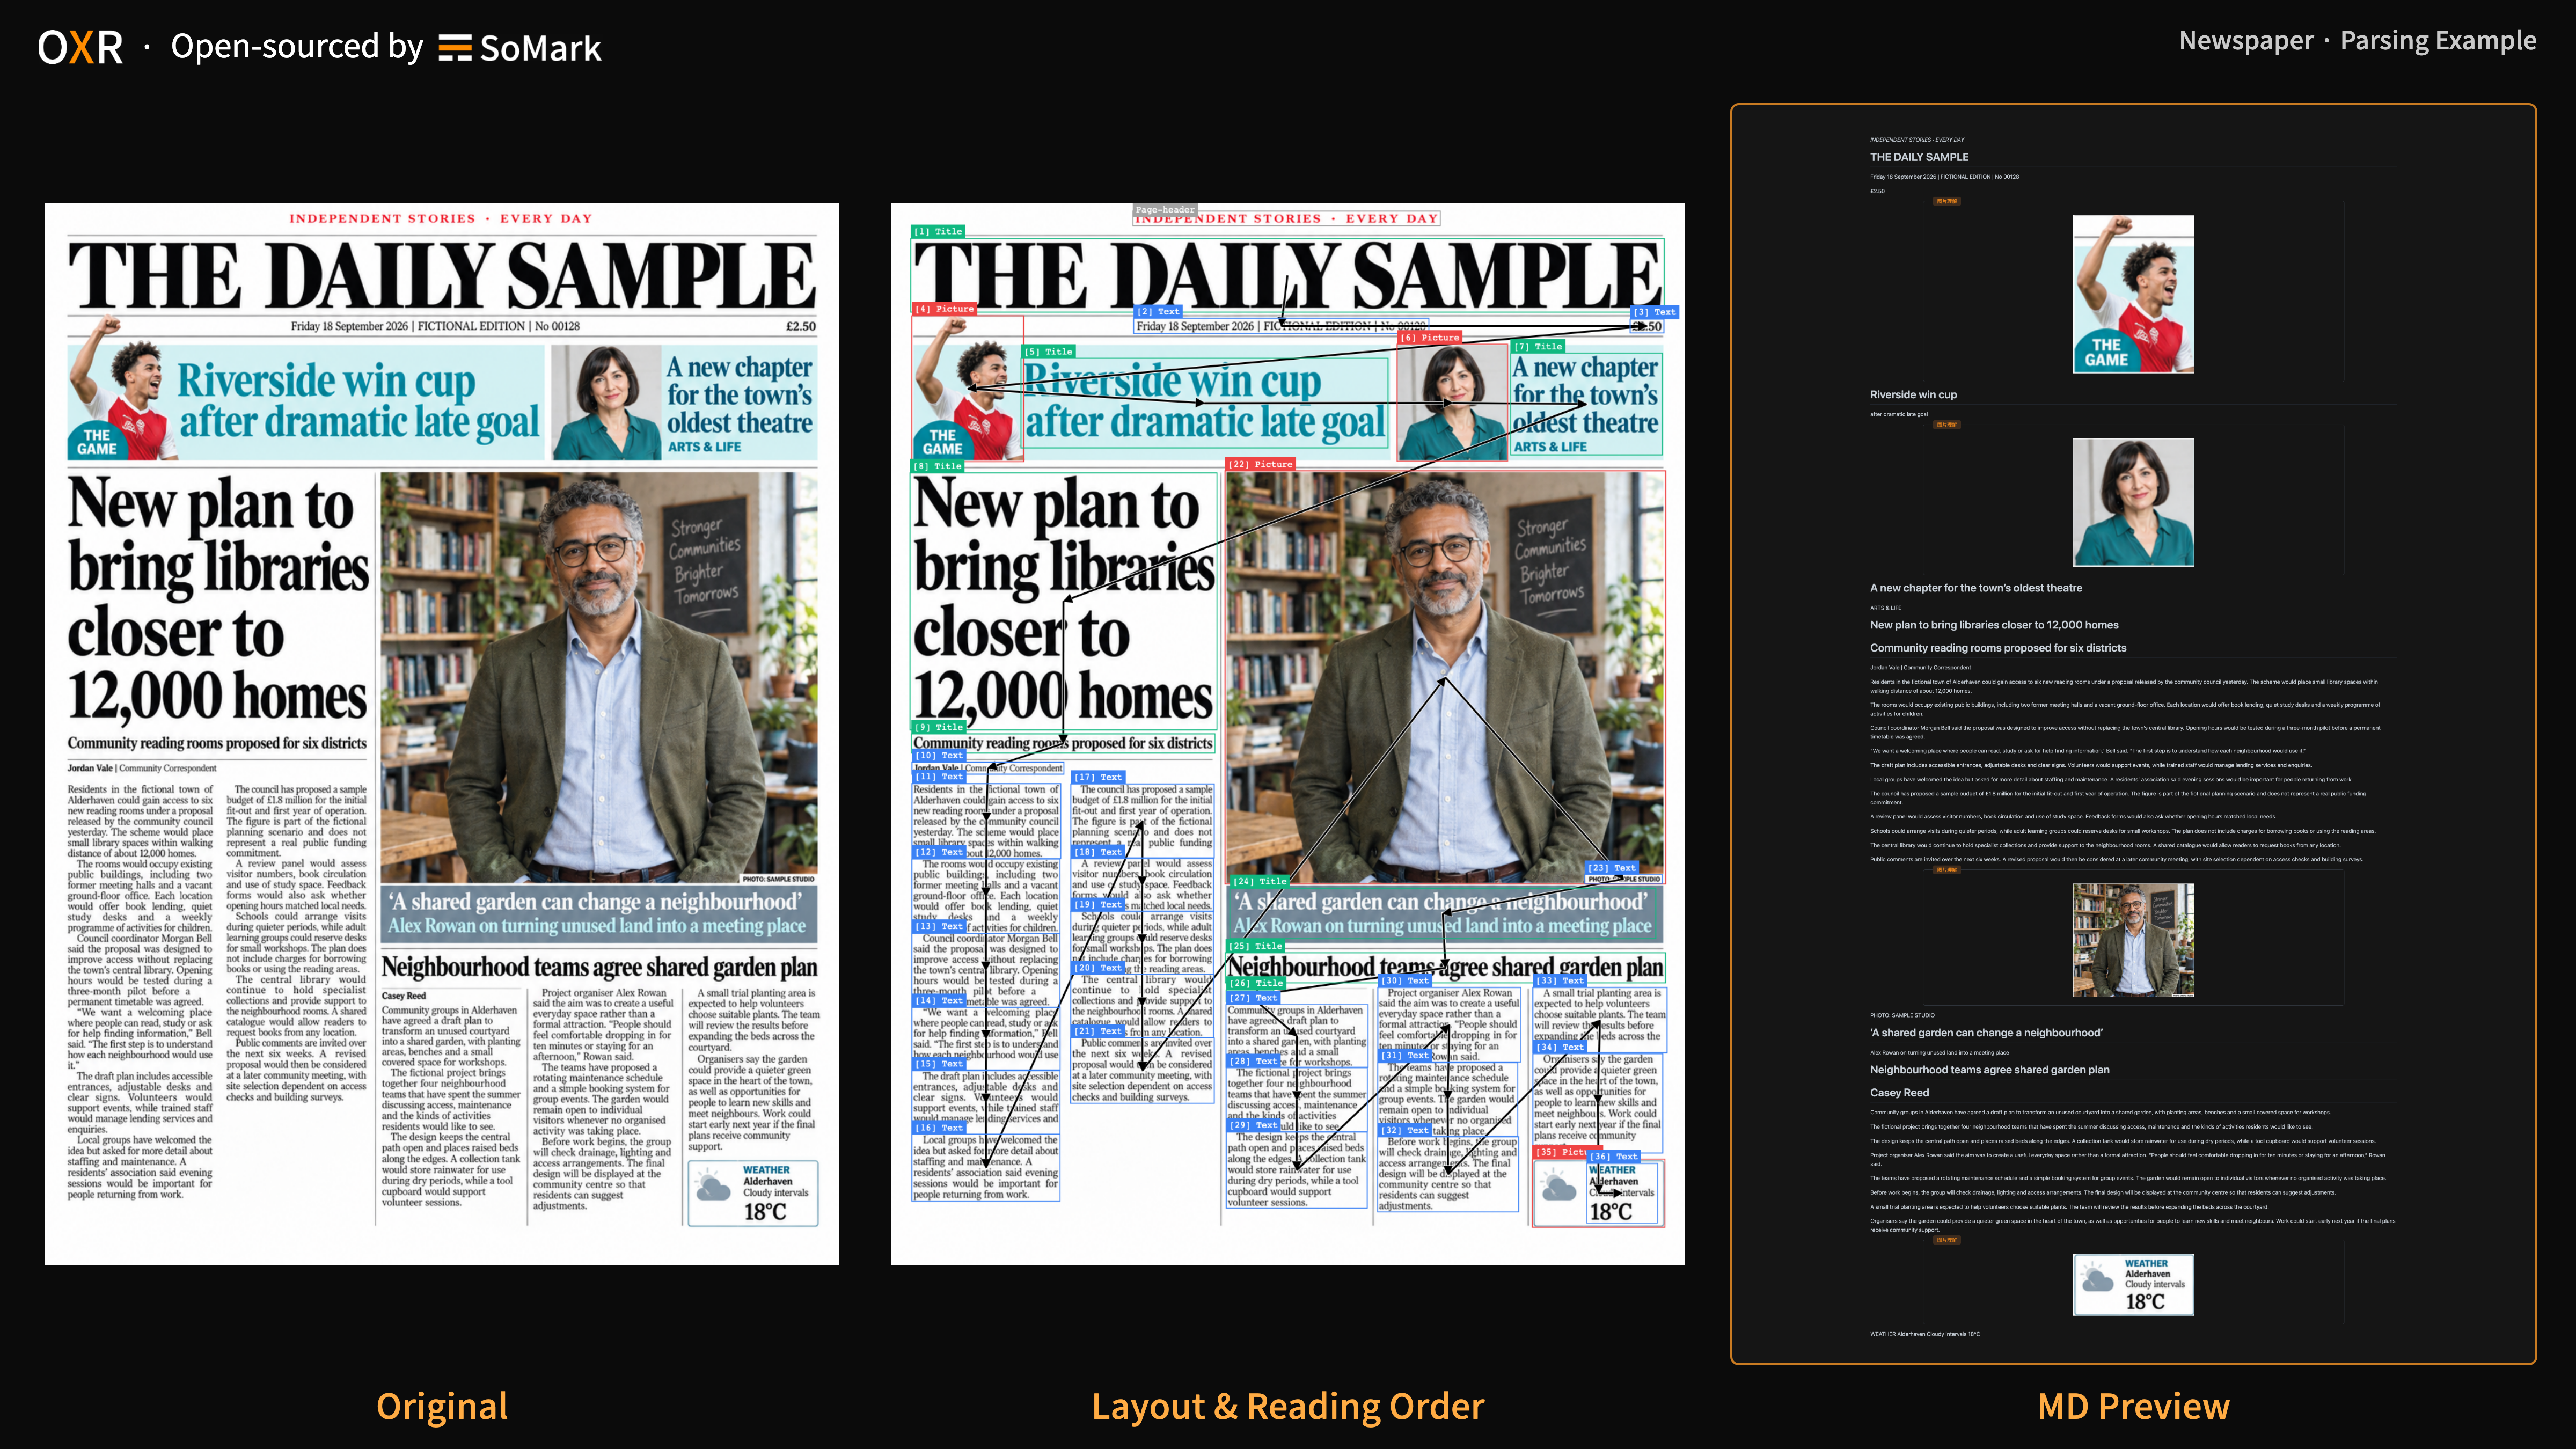
- OXR can recognize 13 document element types, from formulas and tables to chemical equations, chemical structures, and code blocks, with bounding box coordinates included. It also performs well on challenging documents and layouts, including A3 exam papers, newspapers, vertical text, and handwriting.
- See docs/benchmark.md for the full results and instructions to reproduce the evaluations.
-
🚀 1.3B Parameters. Top-Tier Parsing Speed.
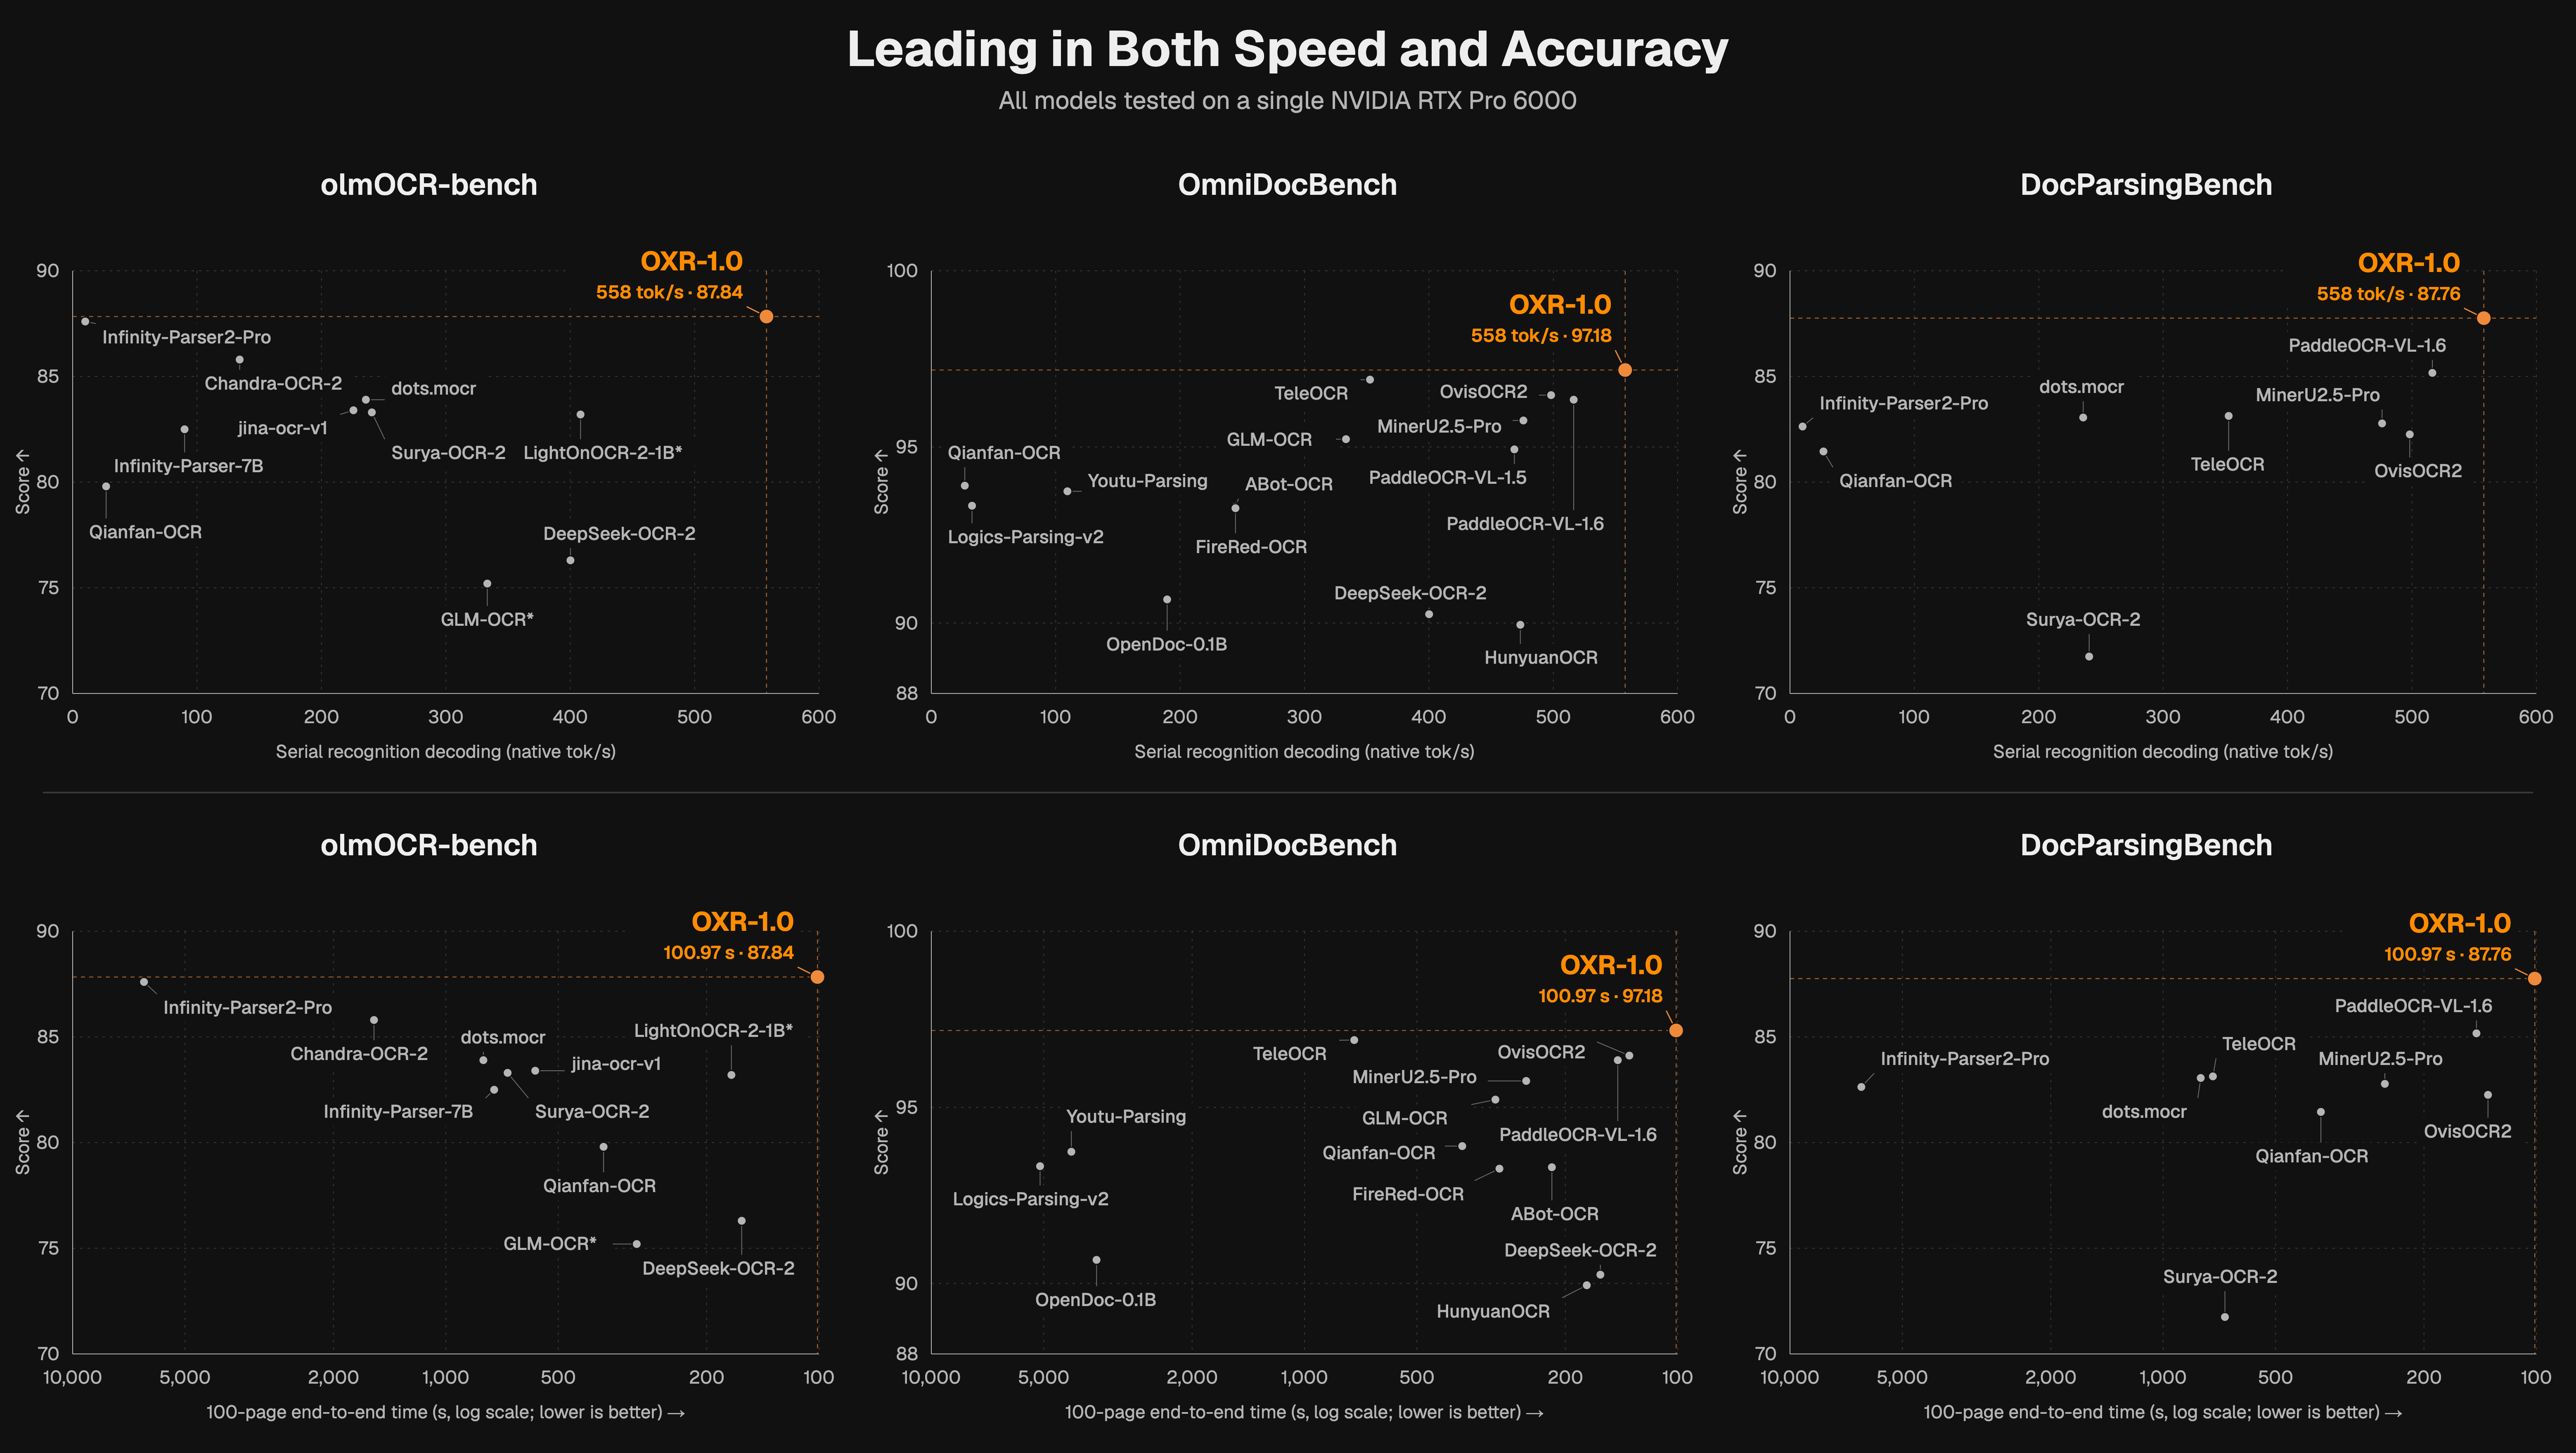
- With only 1.3B parameters, OXR ranks 🏆#1 among open-source document parsing models in speed tests on the RTX PRO 6000.
- OXR redesign its processing architecture at the task level to improve parsing speed while maintaining accuracy.
- See docs/benchmark.md for the full results and instructions to reproduce the evaluations.
-
🧩 Pluggable Layout Analysis. Document Structure on Your Terms.
- Layout analysis requirements vary widely across domains. Even for the same document, element types, region boundaries, and grouping rules can differ depending on the business use case.
- OXR is the first to make layout analysis independent and pluggable. Its built-in layout model can be replaced while retaining OXR’s recognition and reading order capabilities, enabling adaptation across document scenarios with minimal integration effort.
- See the How it works section below for details.
Expand to see all 13 element types
| Name | JSON type value | Content or output format |
|---|---|---|
| Caption | Caption | Plain text |
| Footnote | Footnote | Plain text |
| Formula | Formula | LaTeX |
| Text | Text | Plain text |
| Footer | Page-footer | Plain text (filtered out by default) |
| Header | Page-header | Plain text (filtered out by default) |
| Figure | Picture | Image |
| Title | Title | Plain text |
| Table | Table | HTML / Markdown |
| Stamp | Stamp | Plain text / Image |
| Chemical Equation | Chemical Equation | LaTeX (starting with \ce, using mhchem syntax) |
| Code Block | Code Block | Markdown code block |
| Chemical Structure | Chemical Structure | SMILES / Image |
Parsing Examples
The animation shows OXR's parsing process.
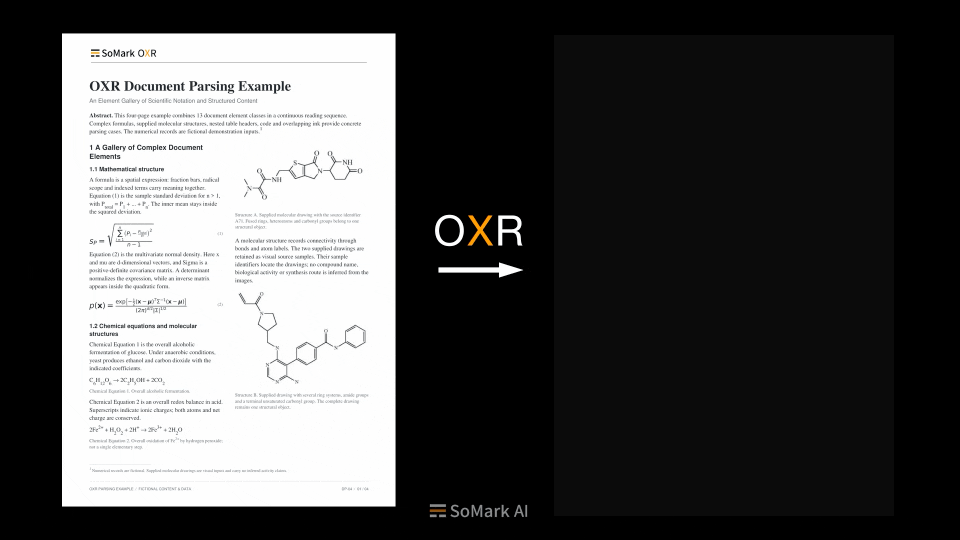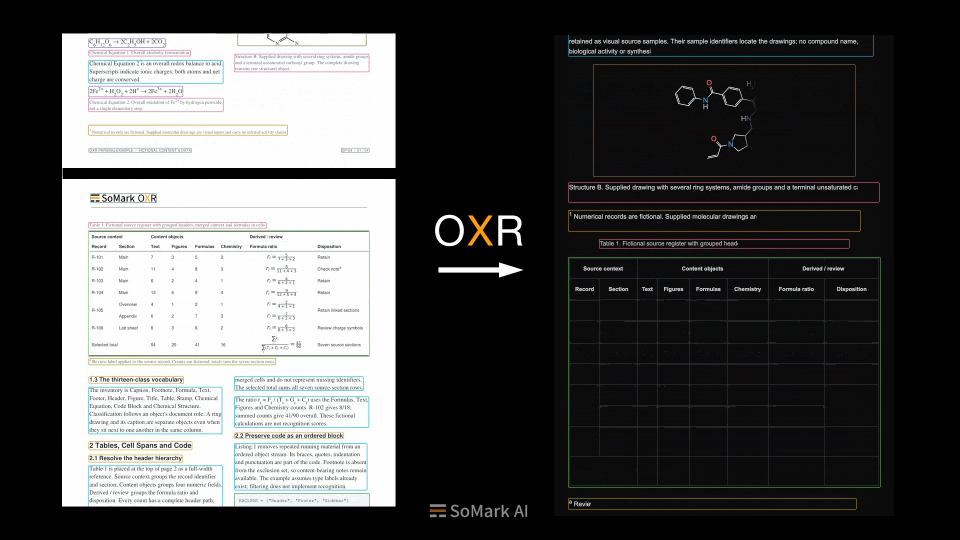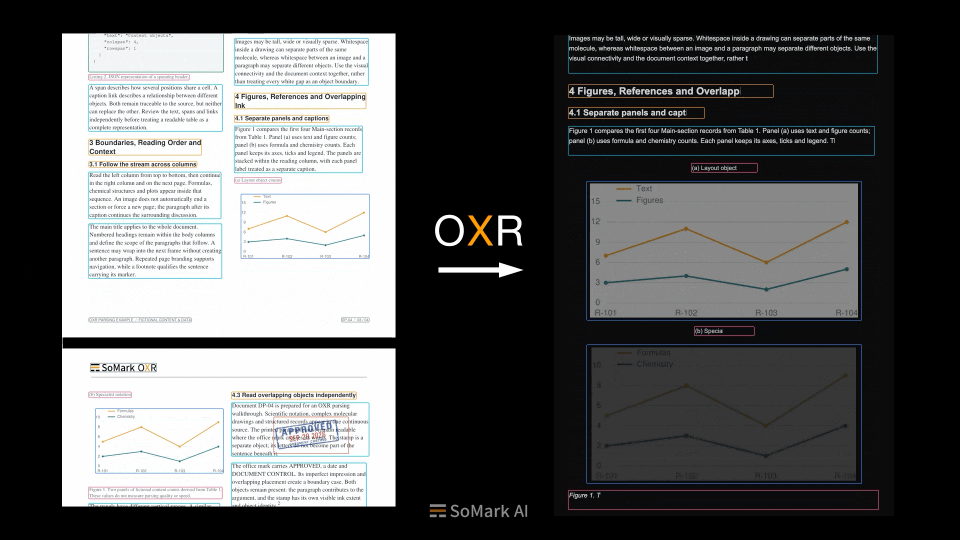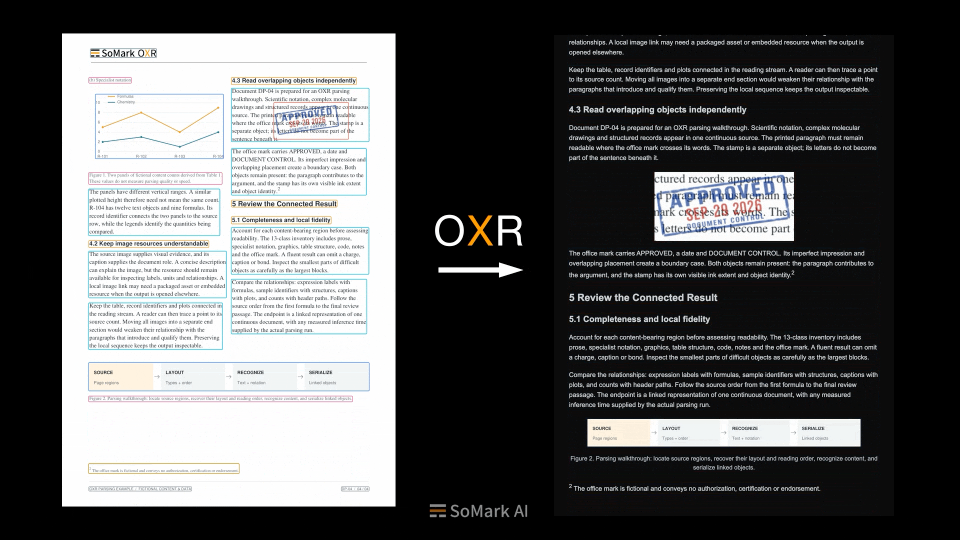
The examples below show OXR parsing different document types. Click an image to view the original.
A3 Exam Paper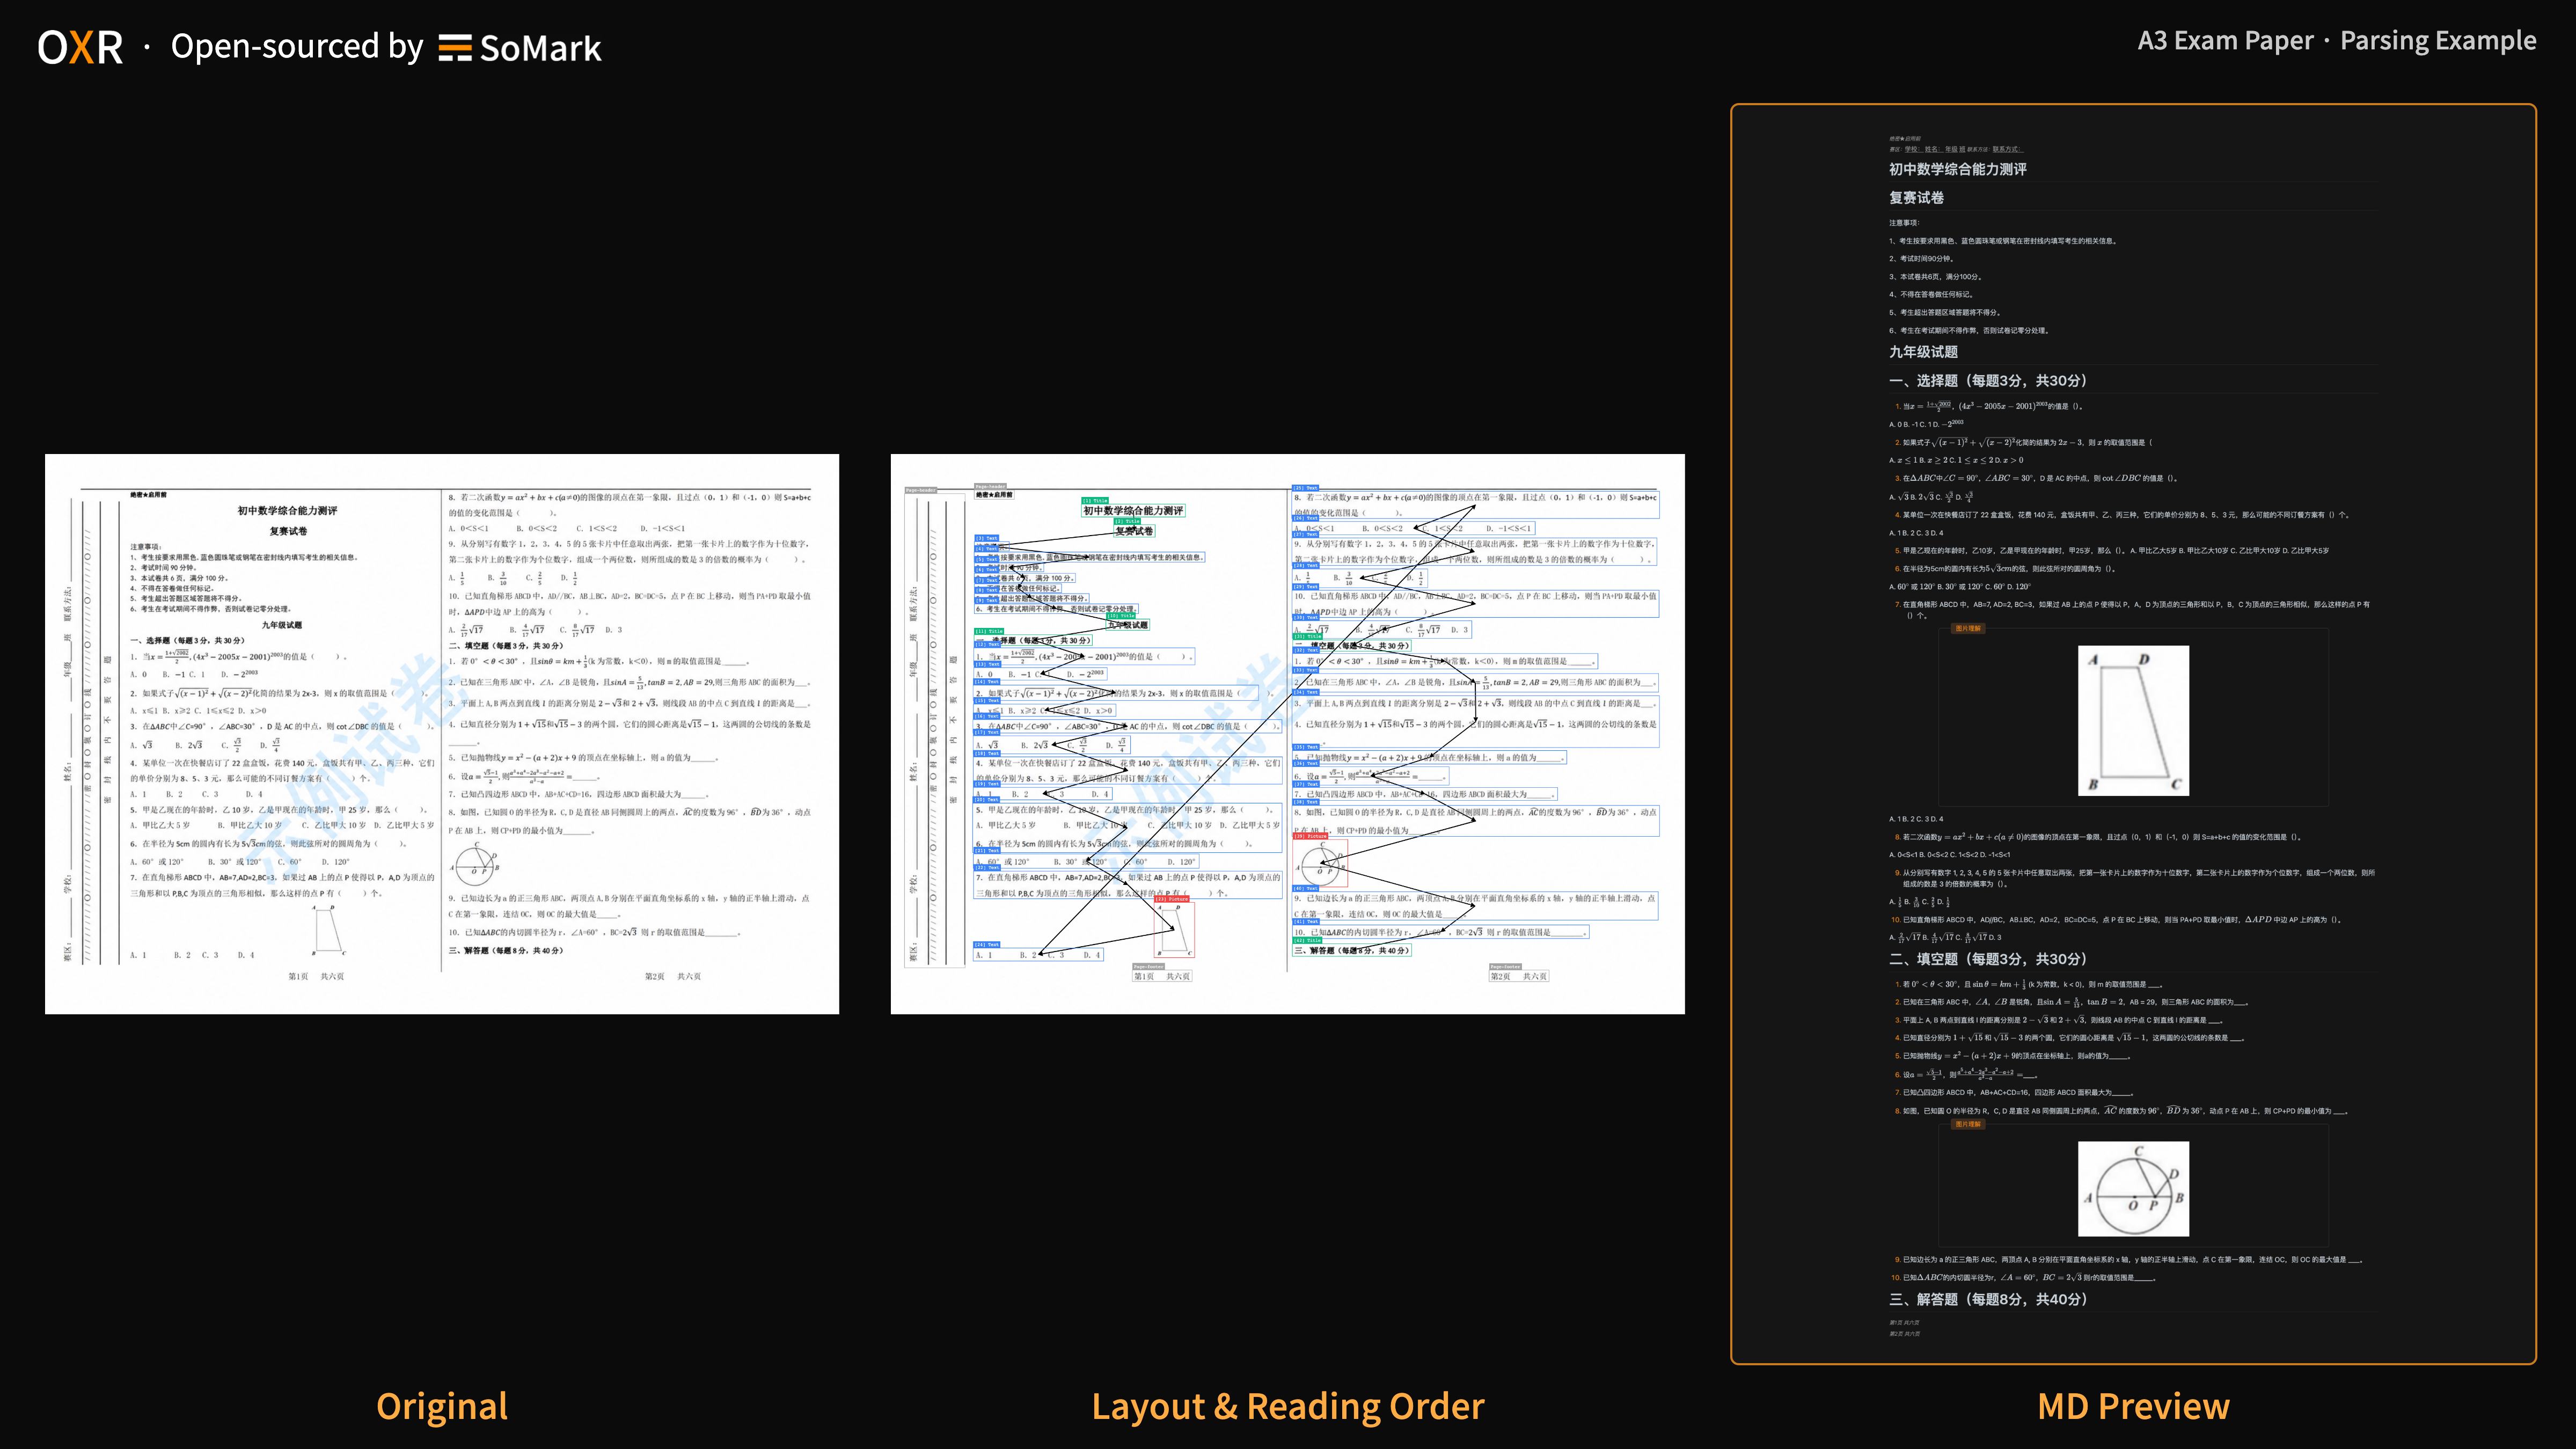 | Chinese Handwriting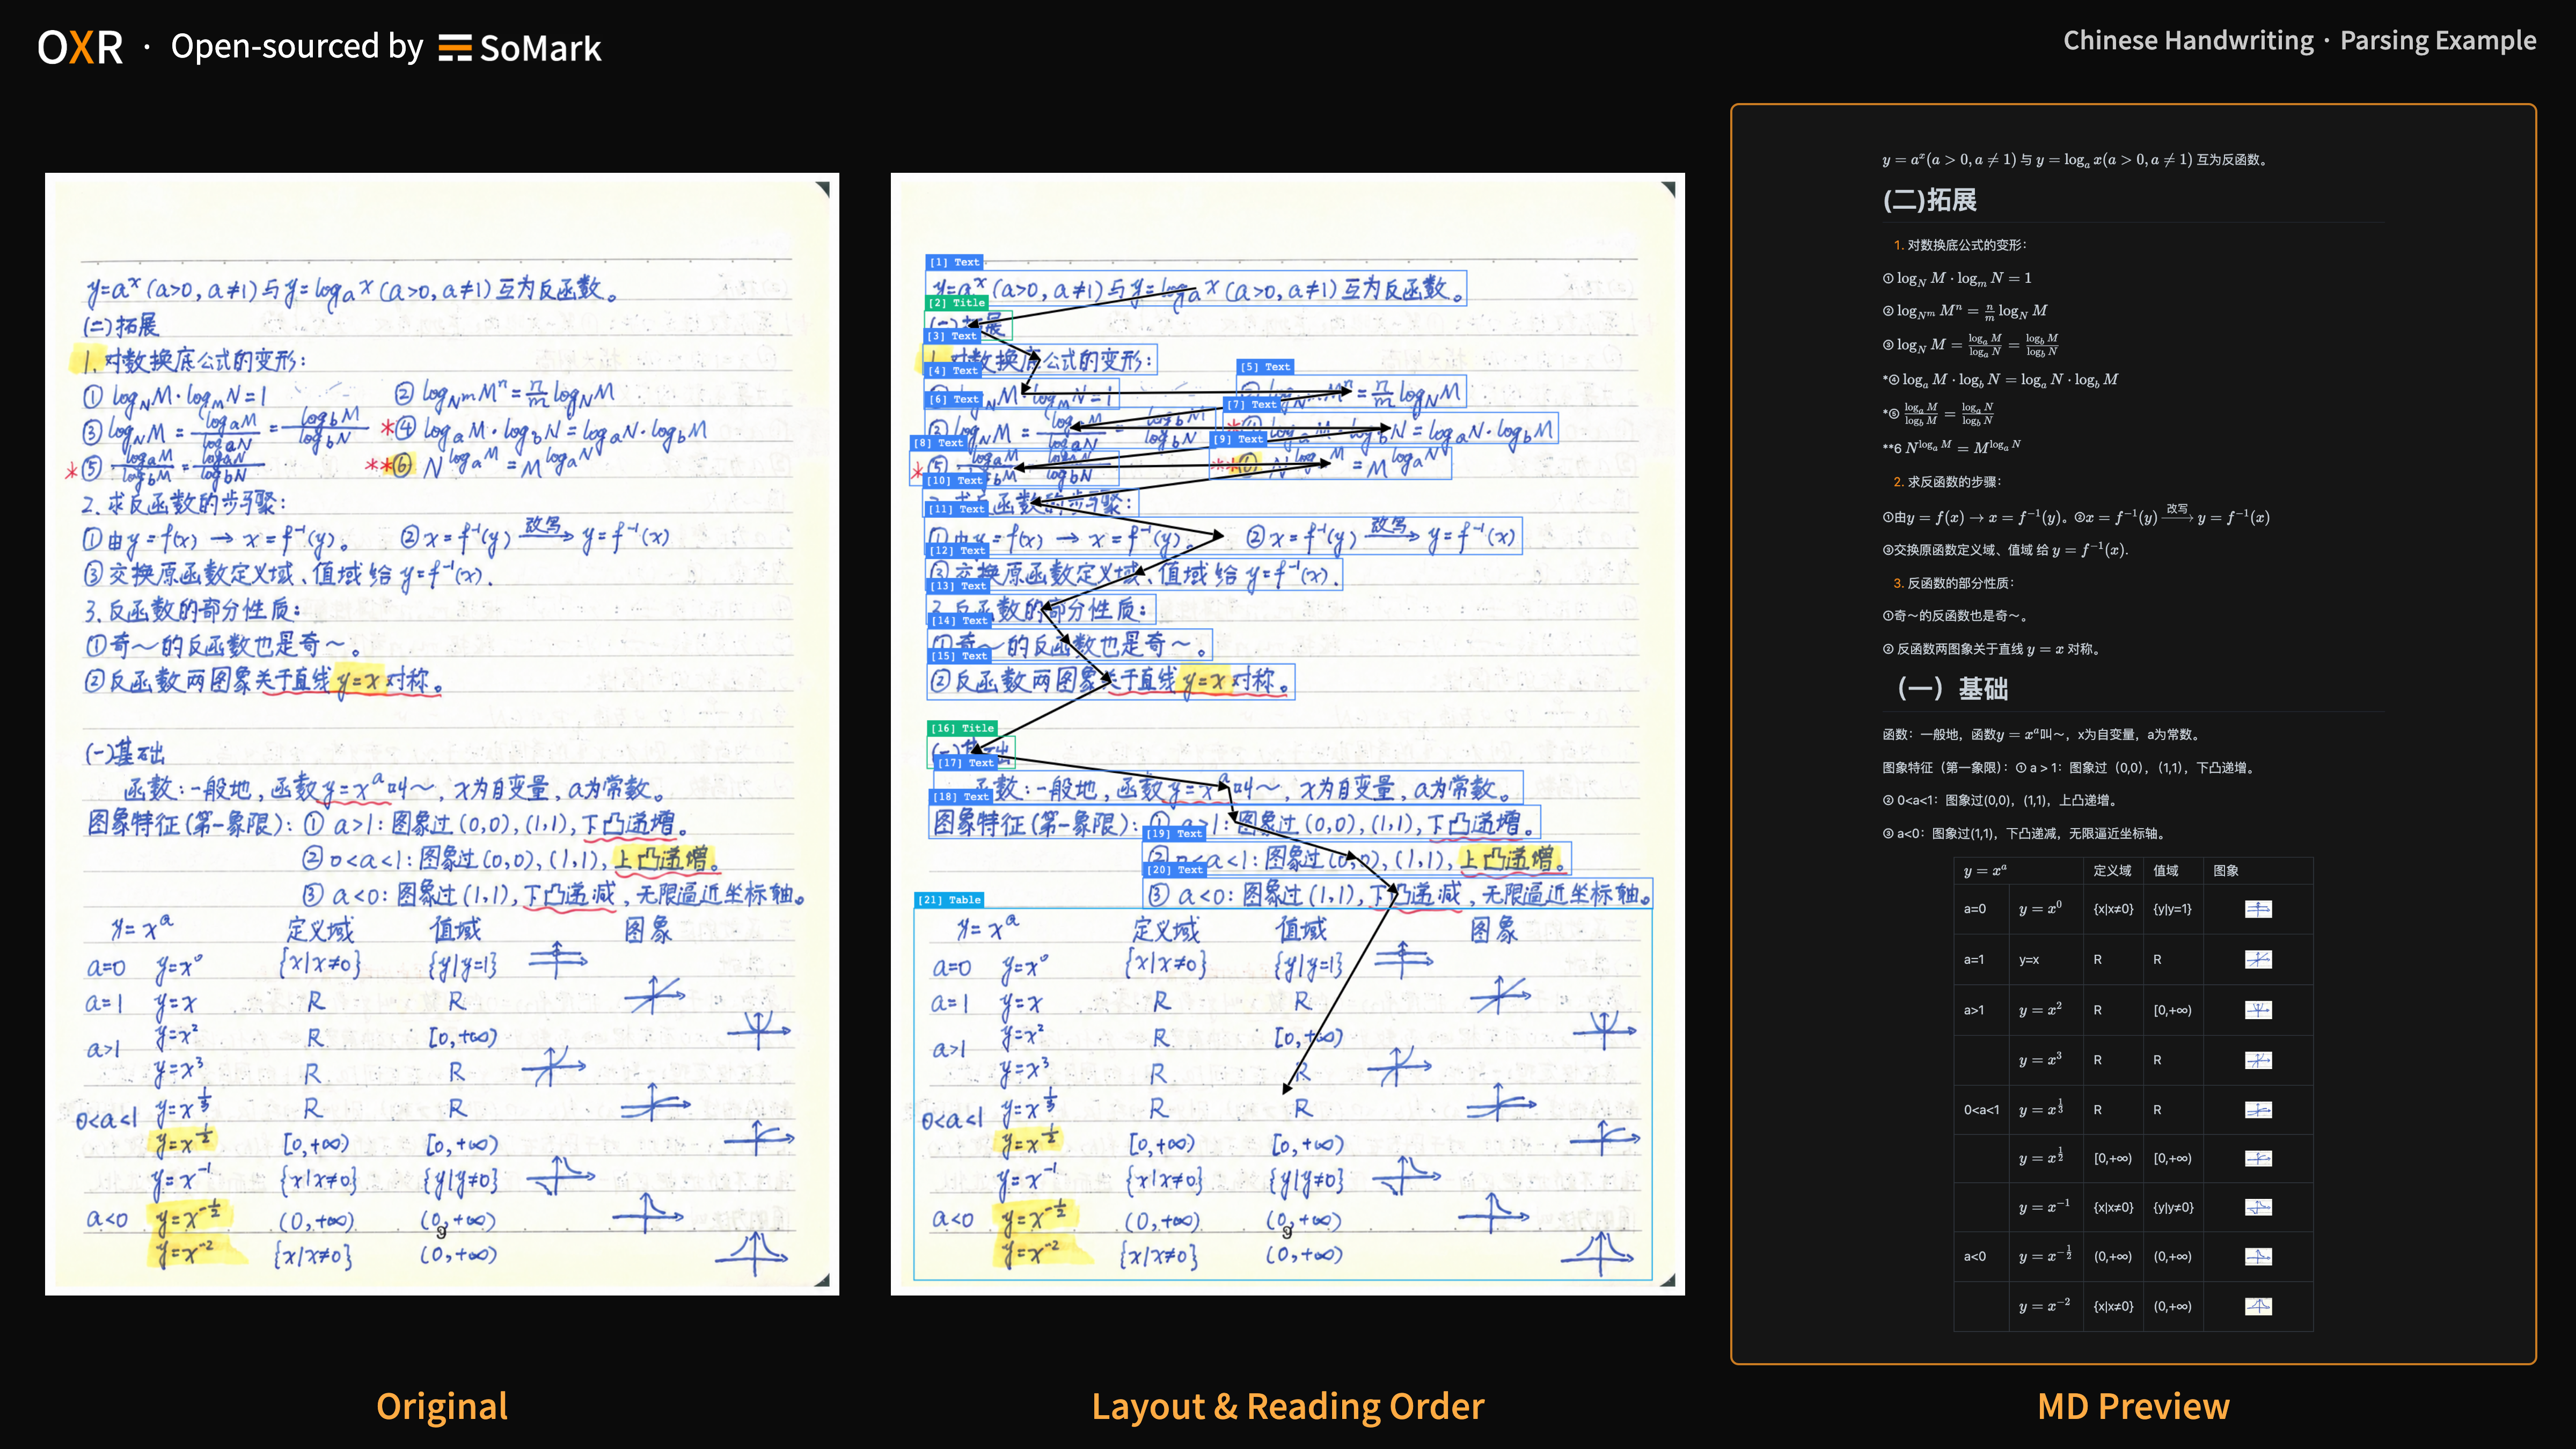 | Code Block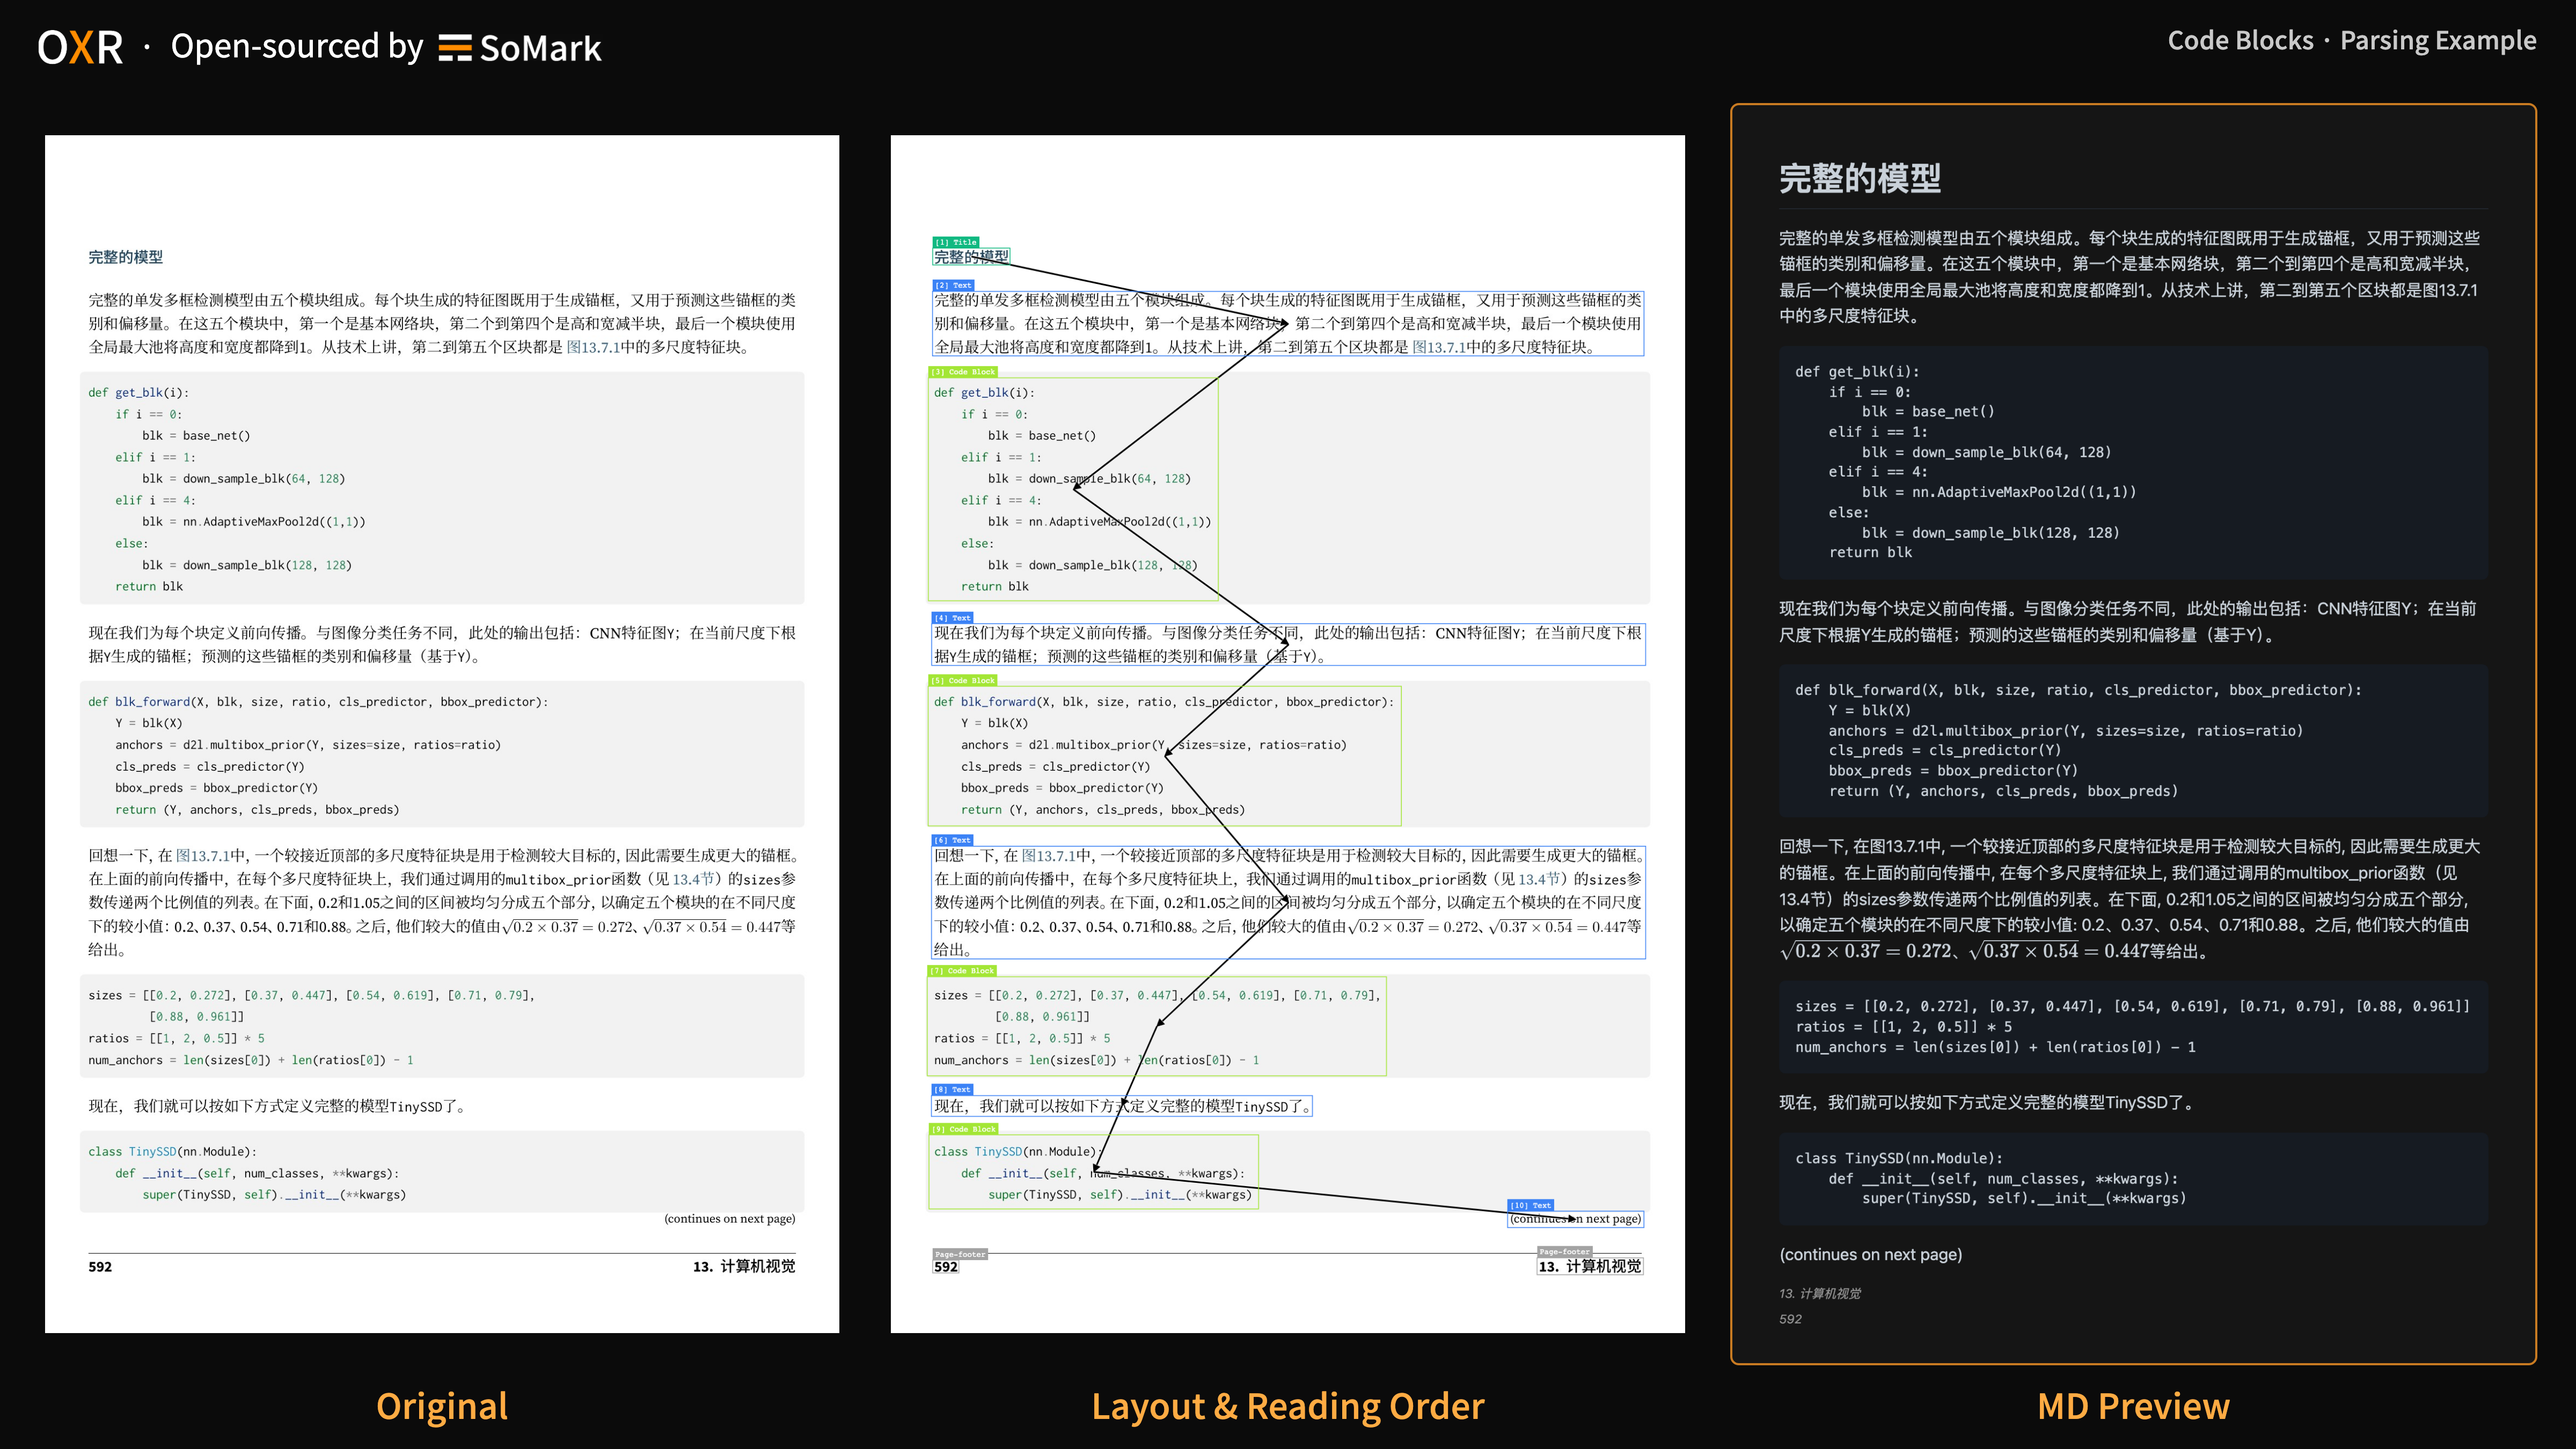 |
Chemical Equation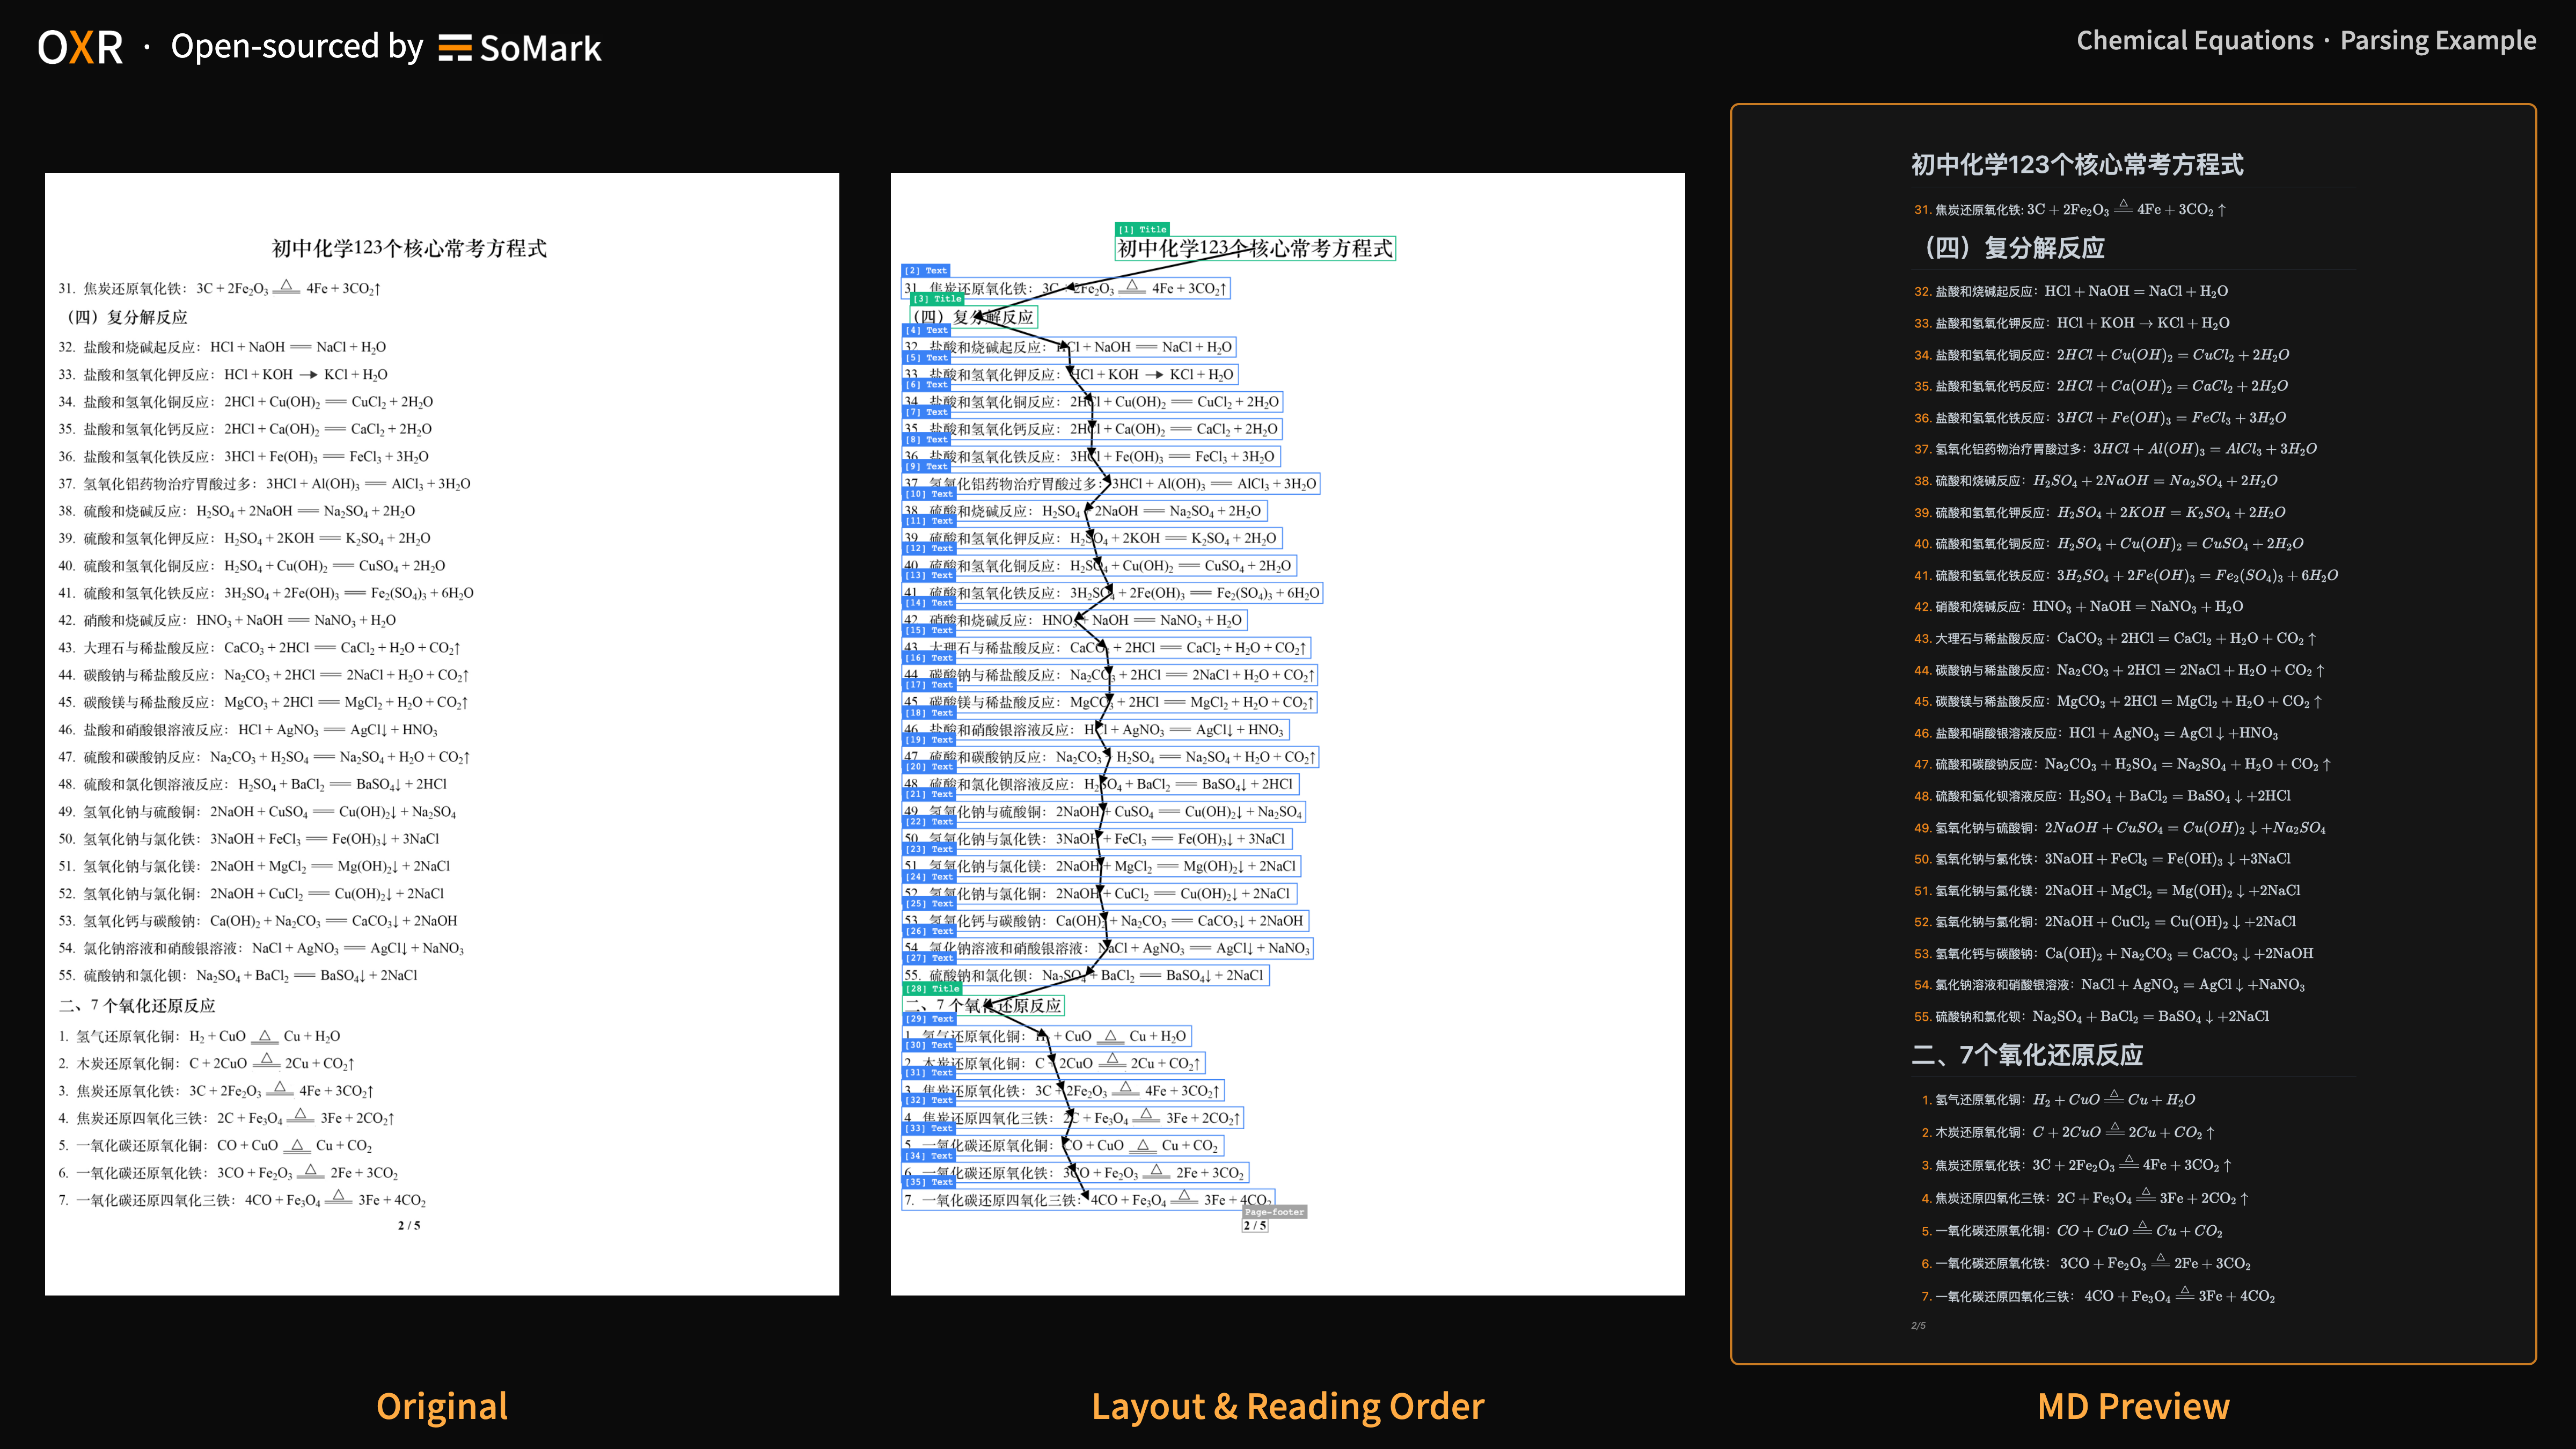 | Chemical Structure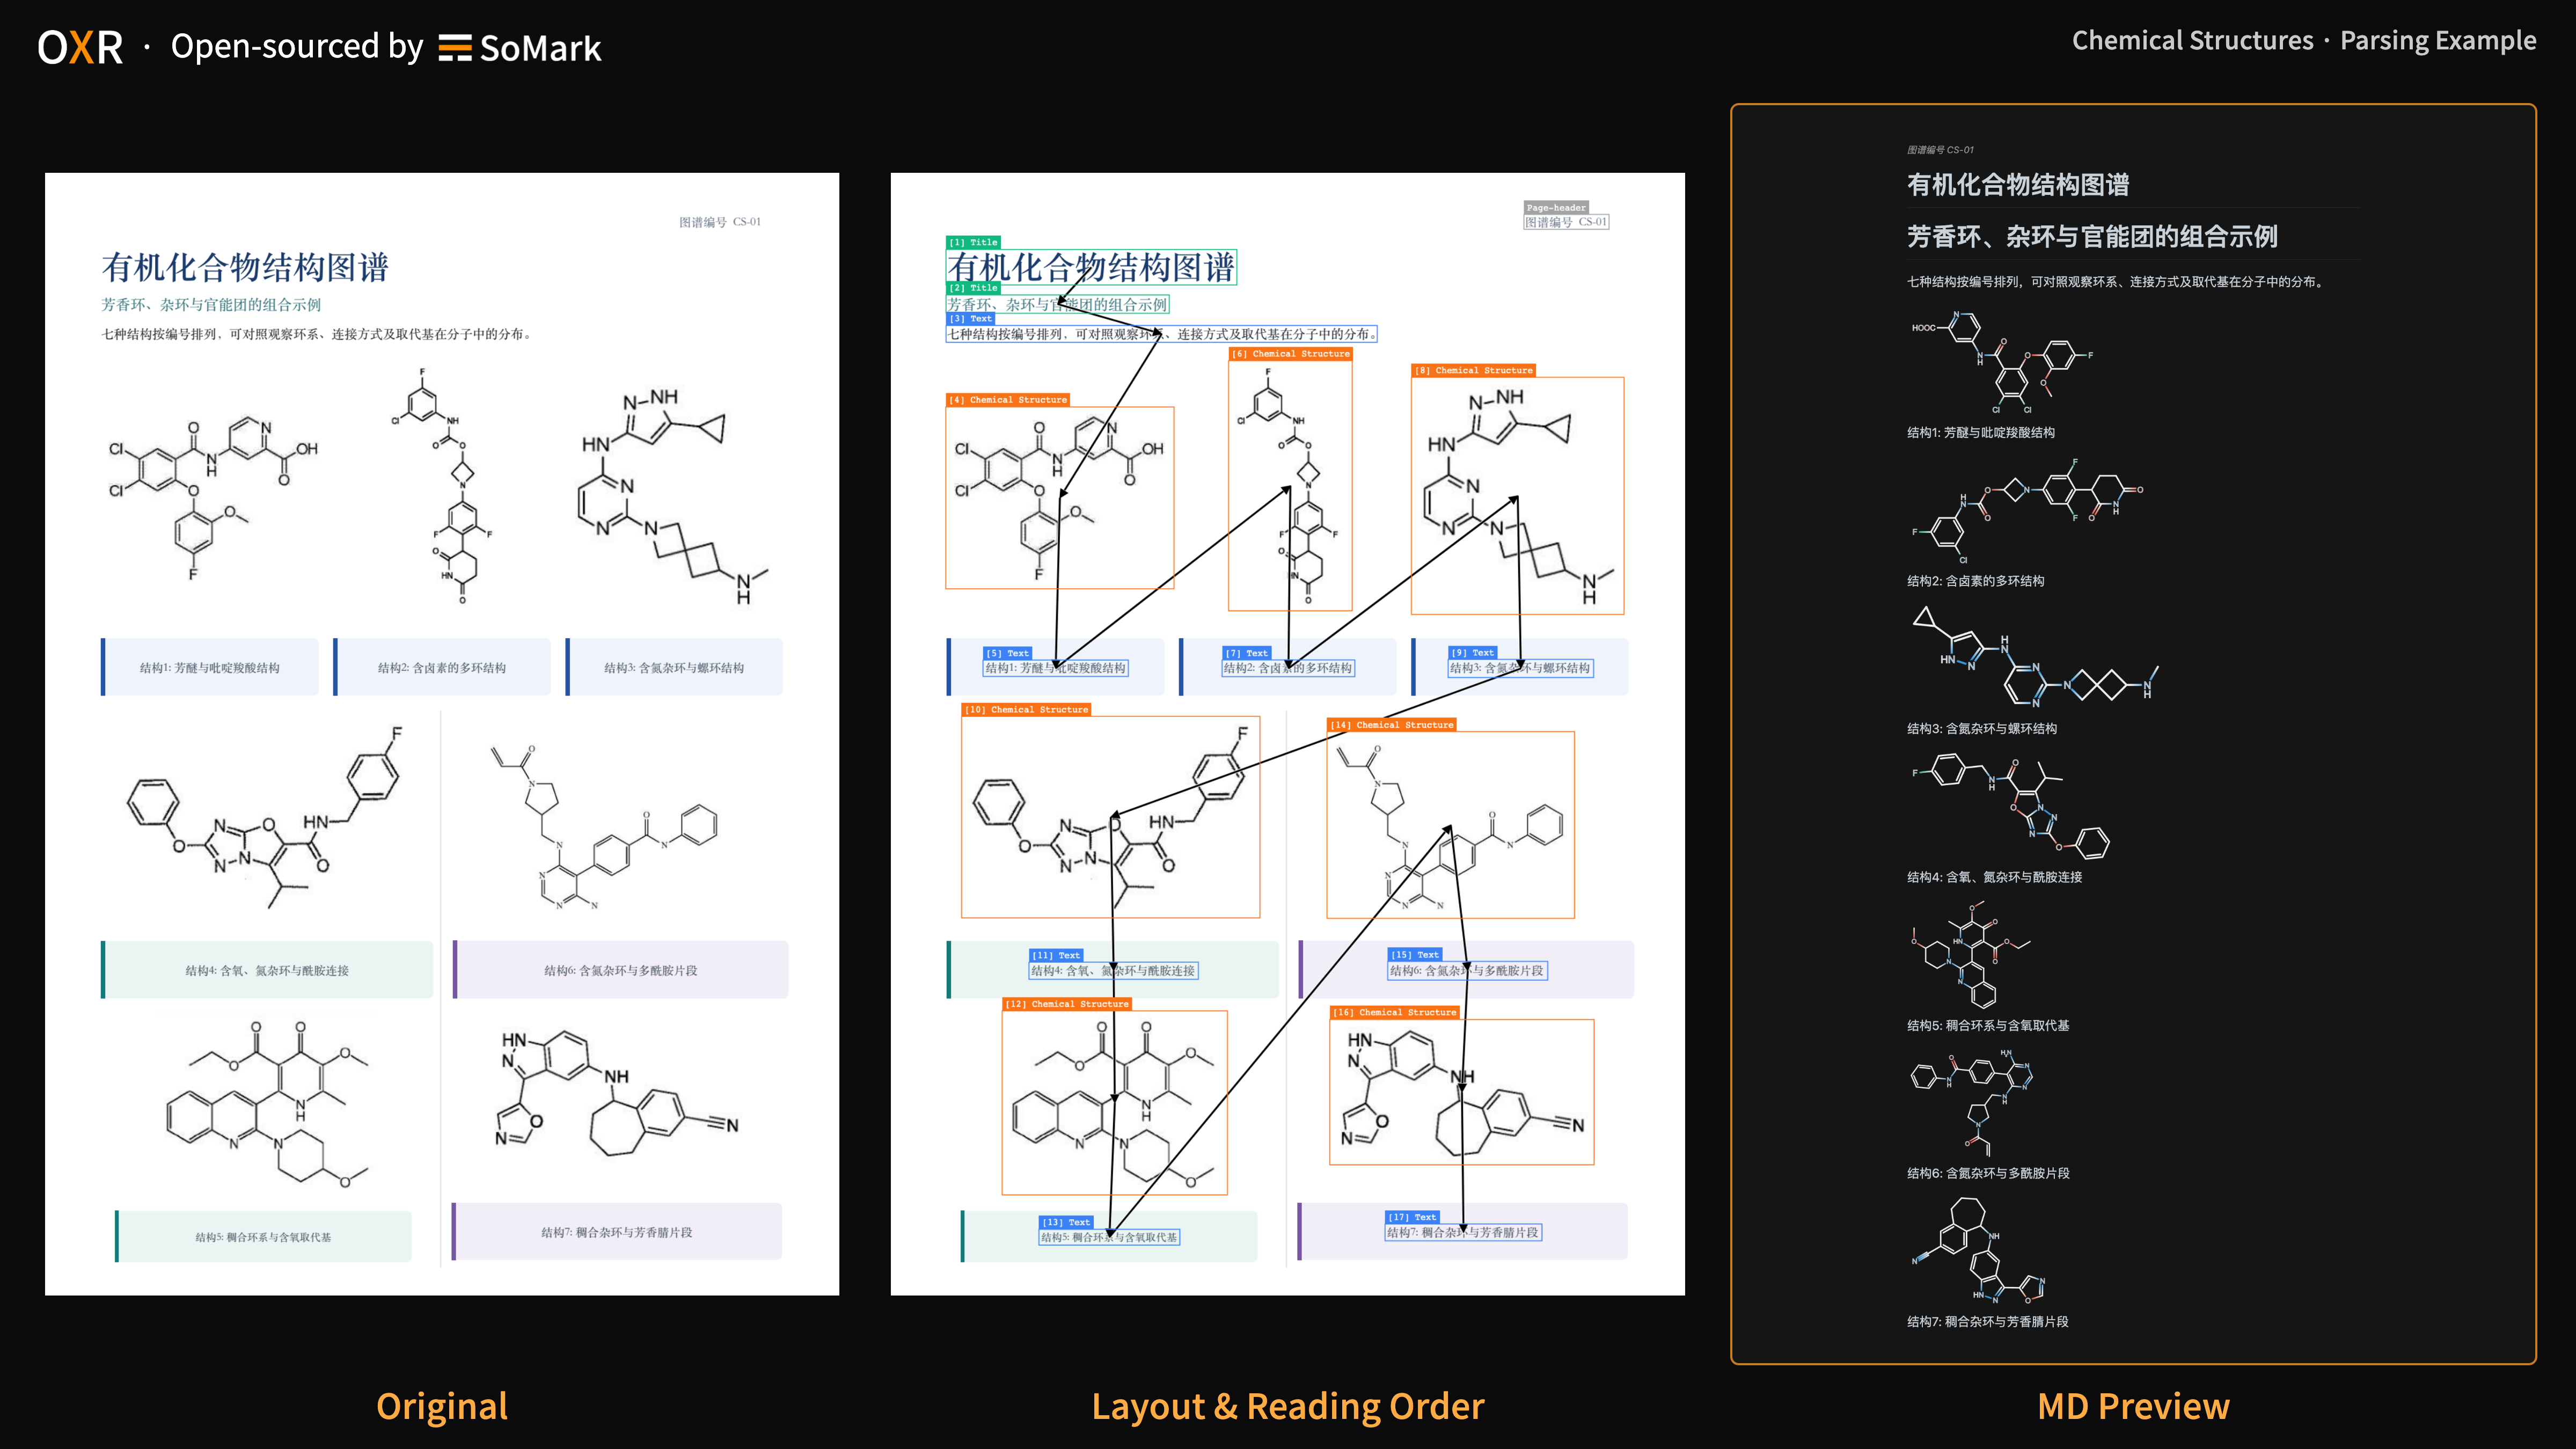 | Complex Formula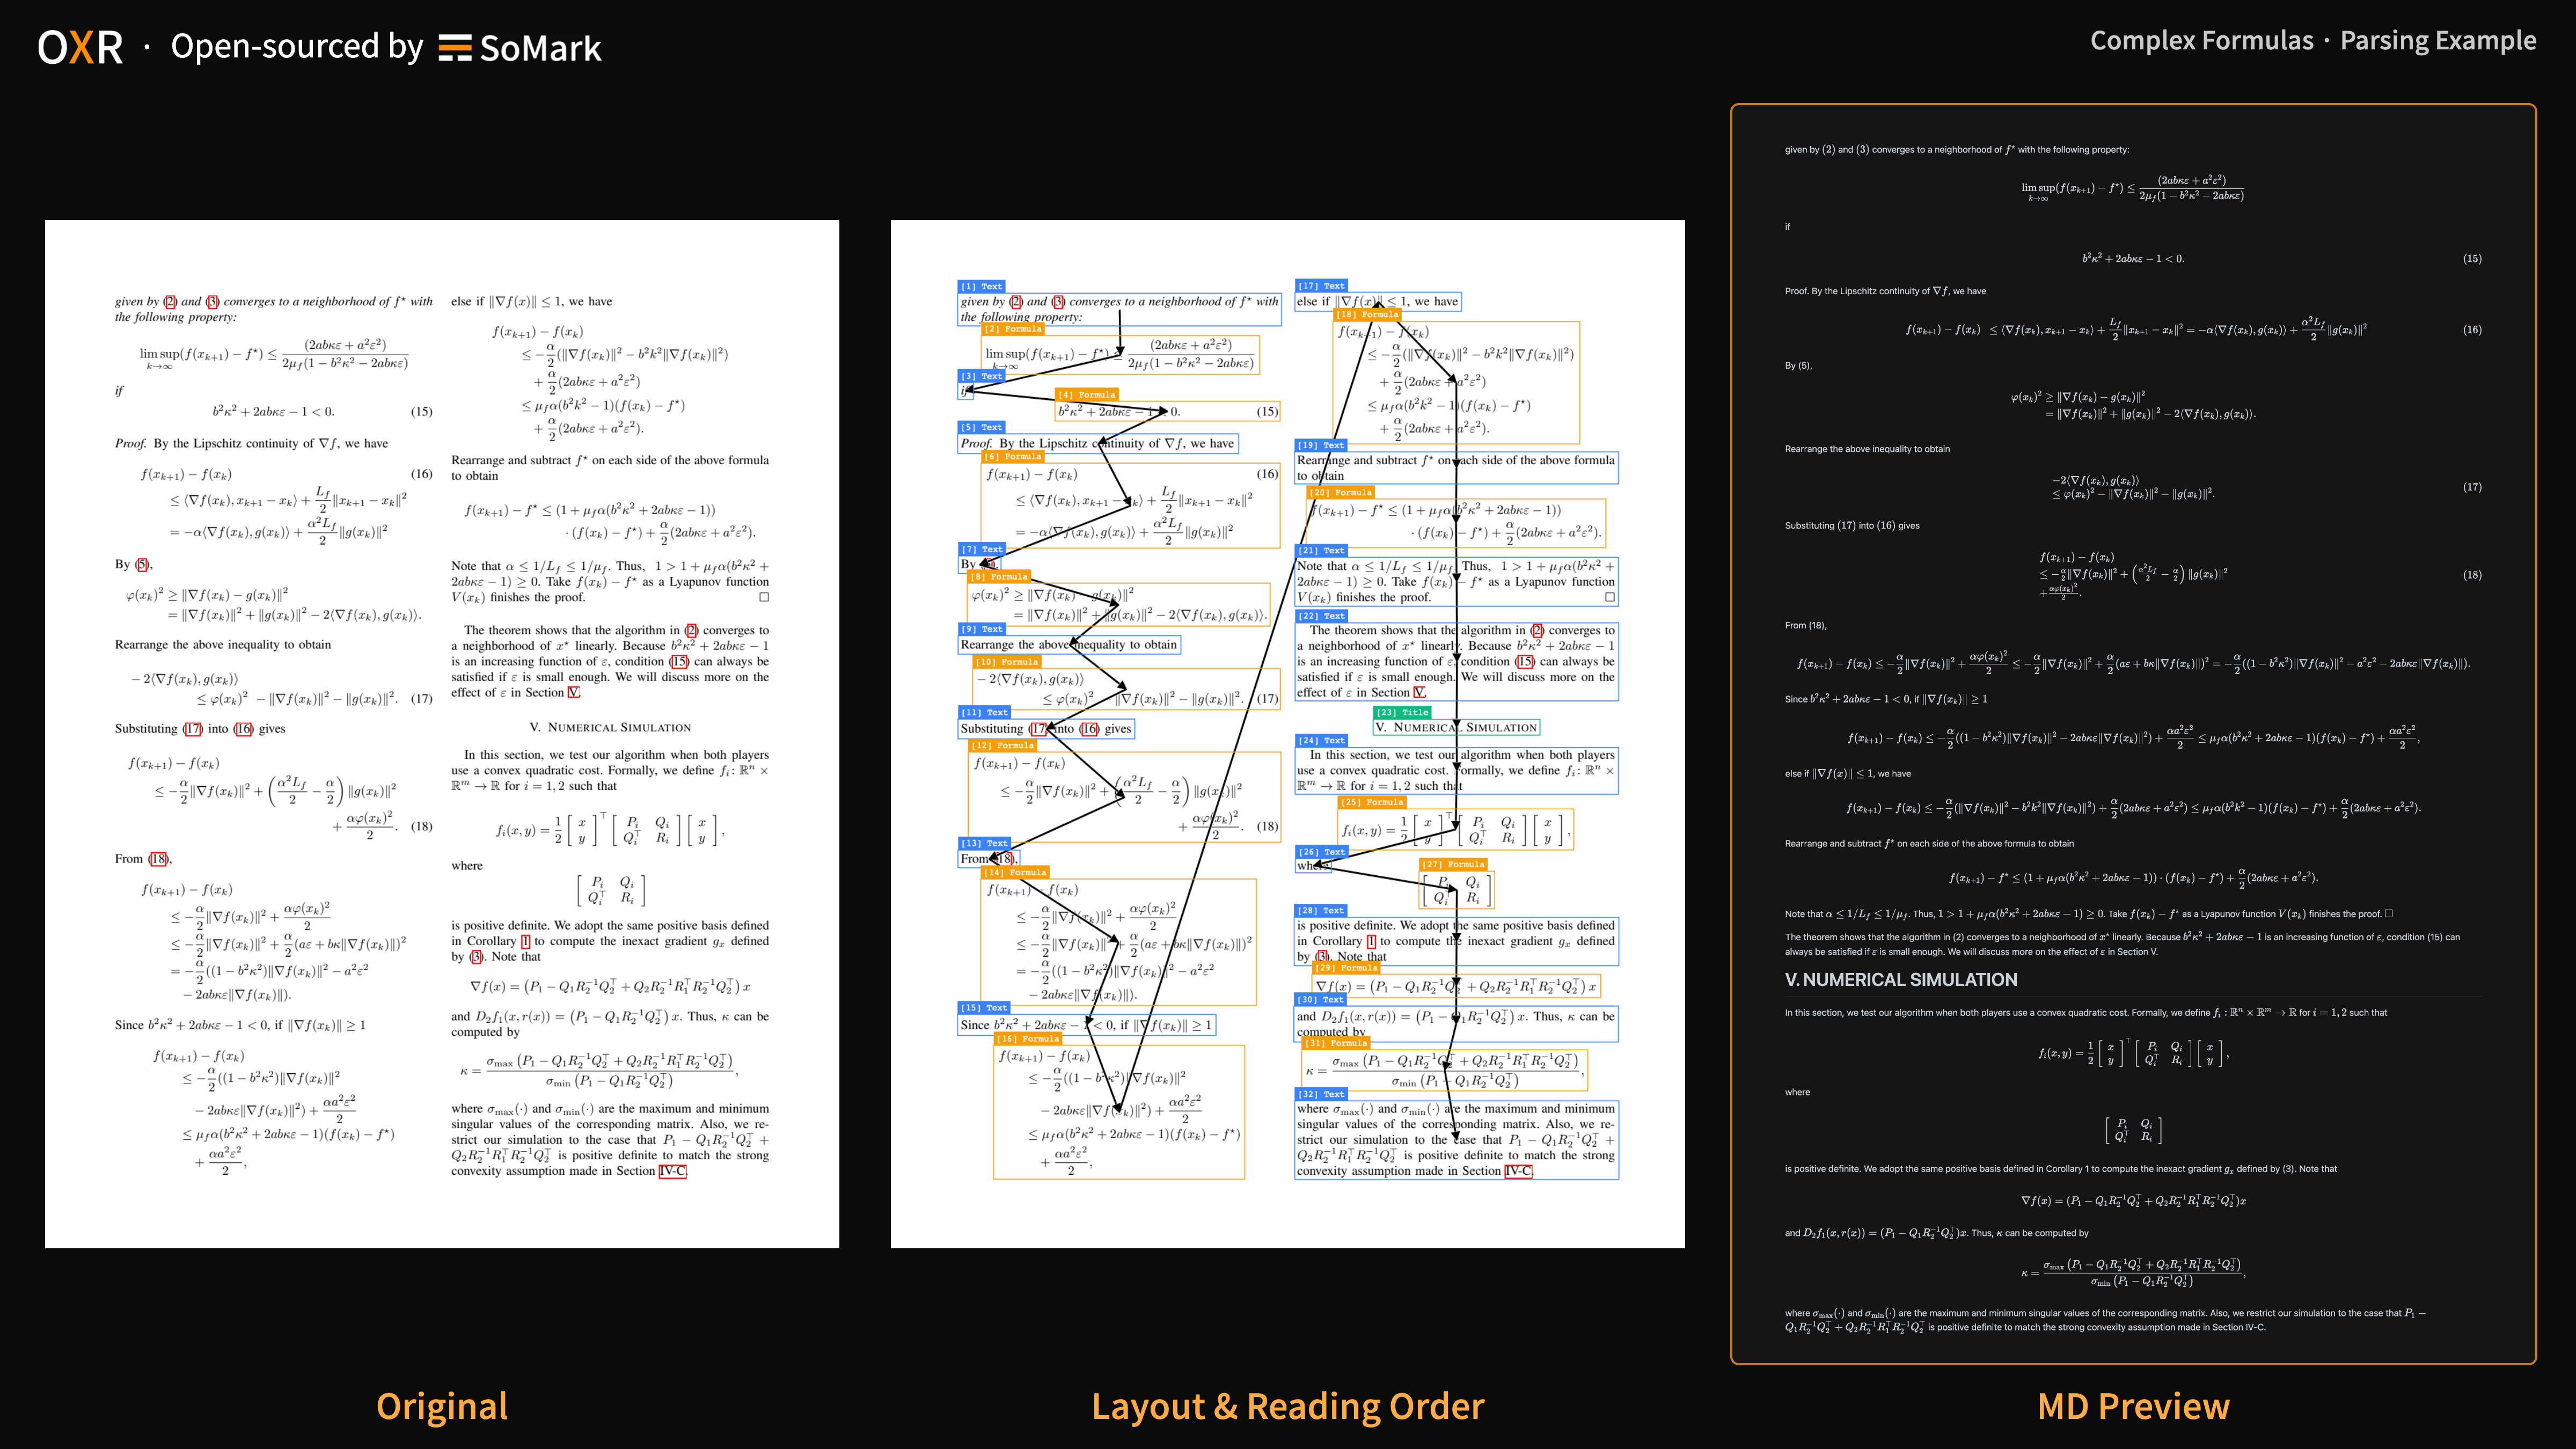 |
Complex Table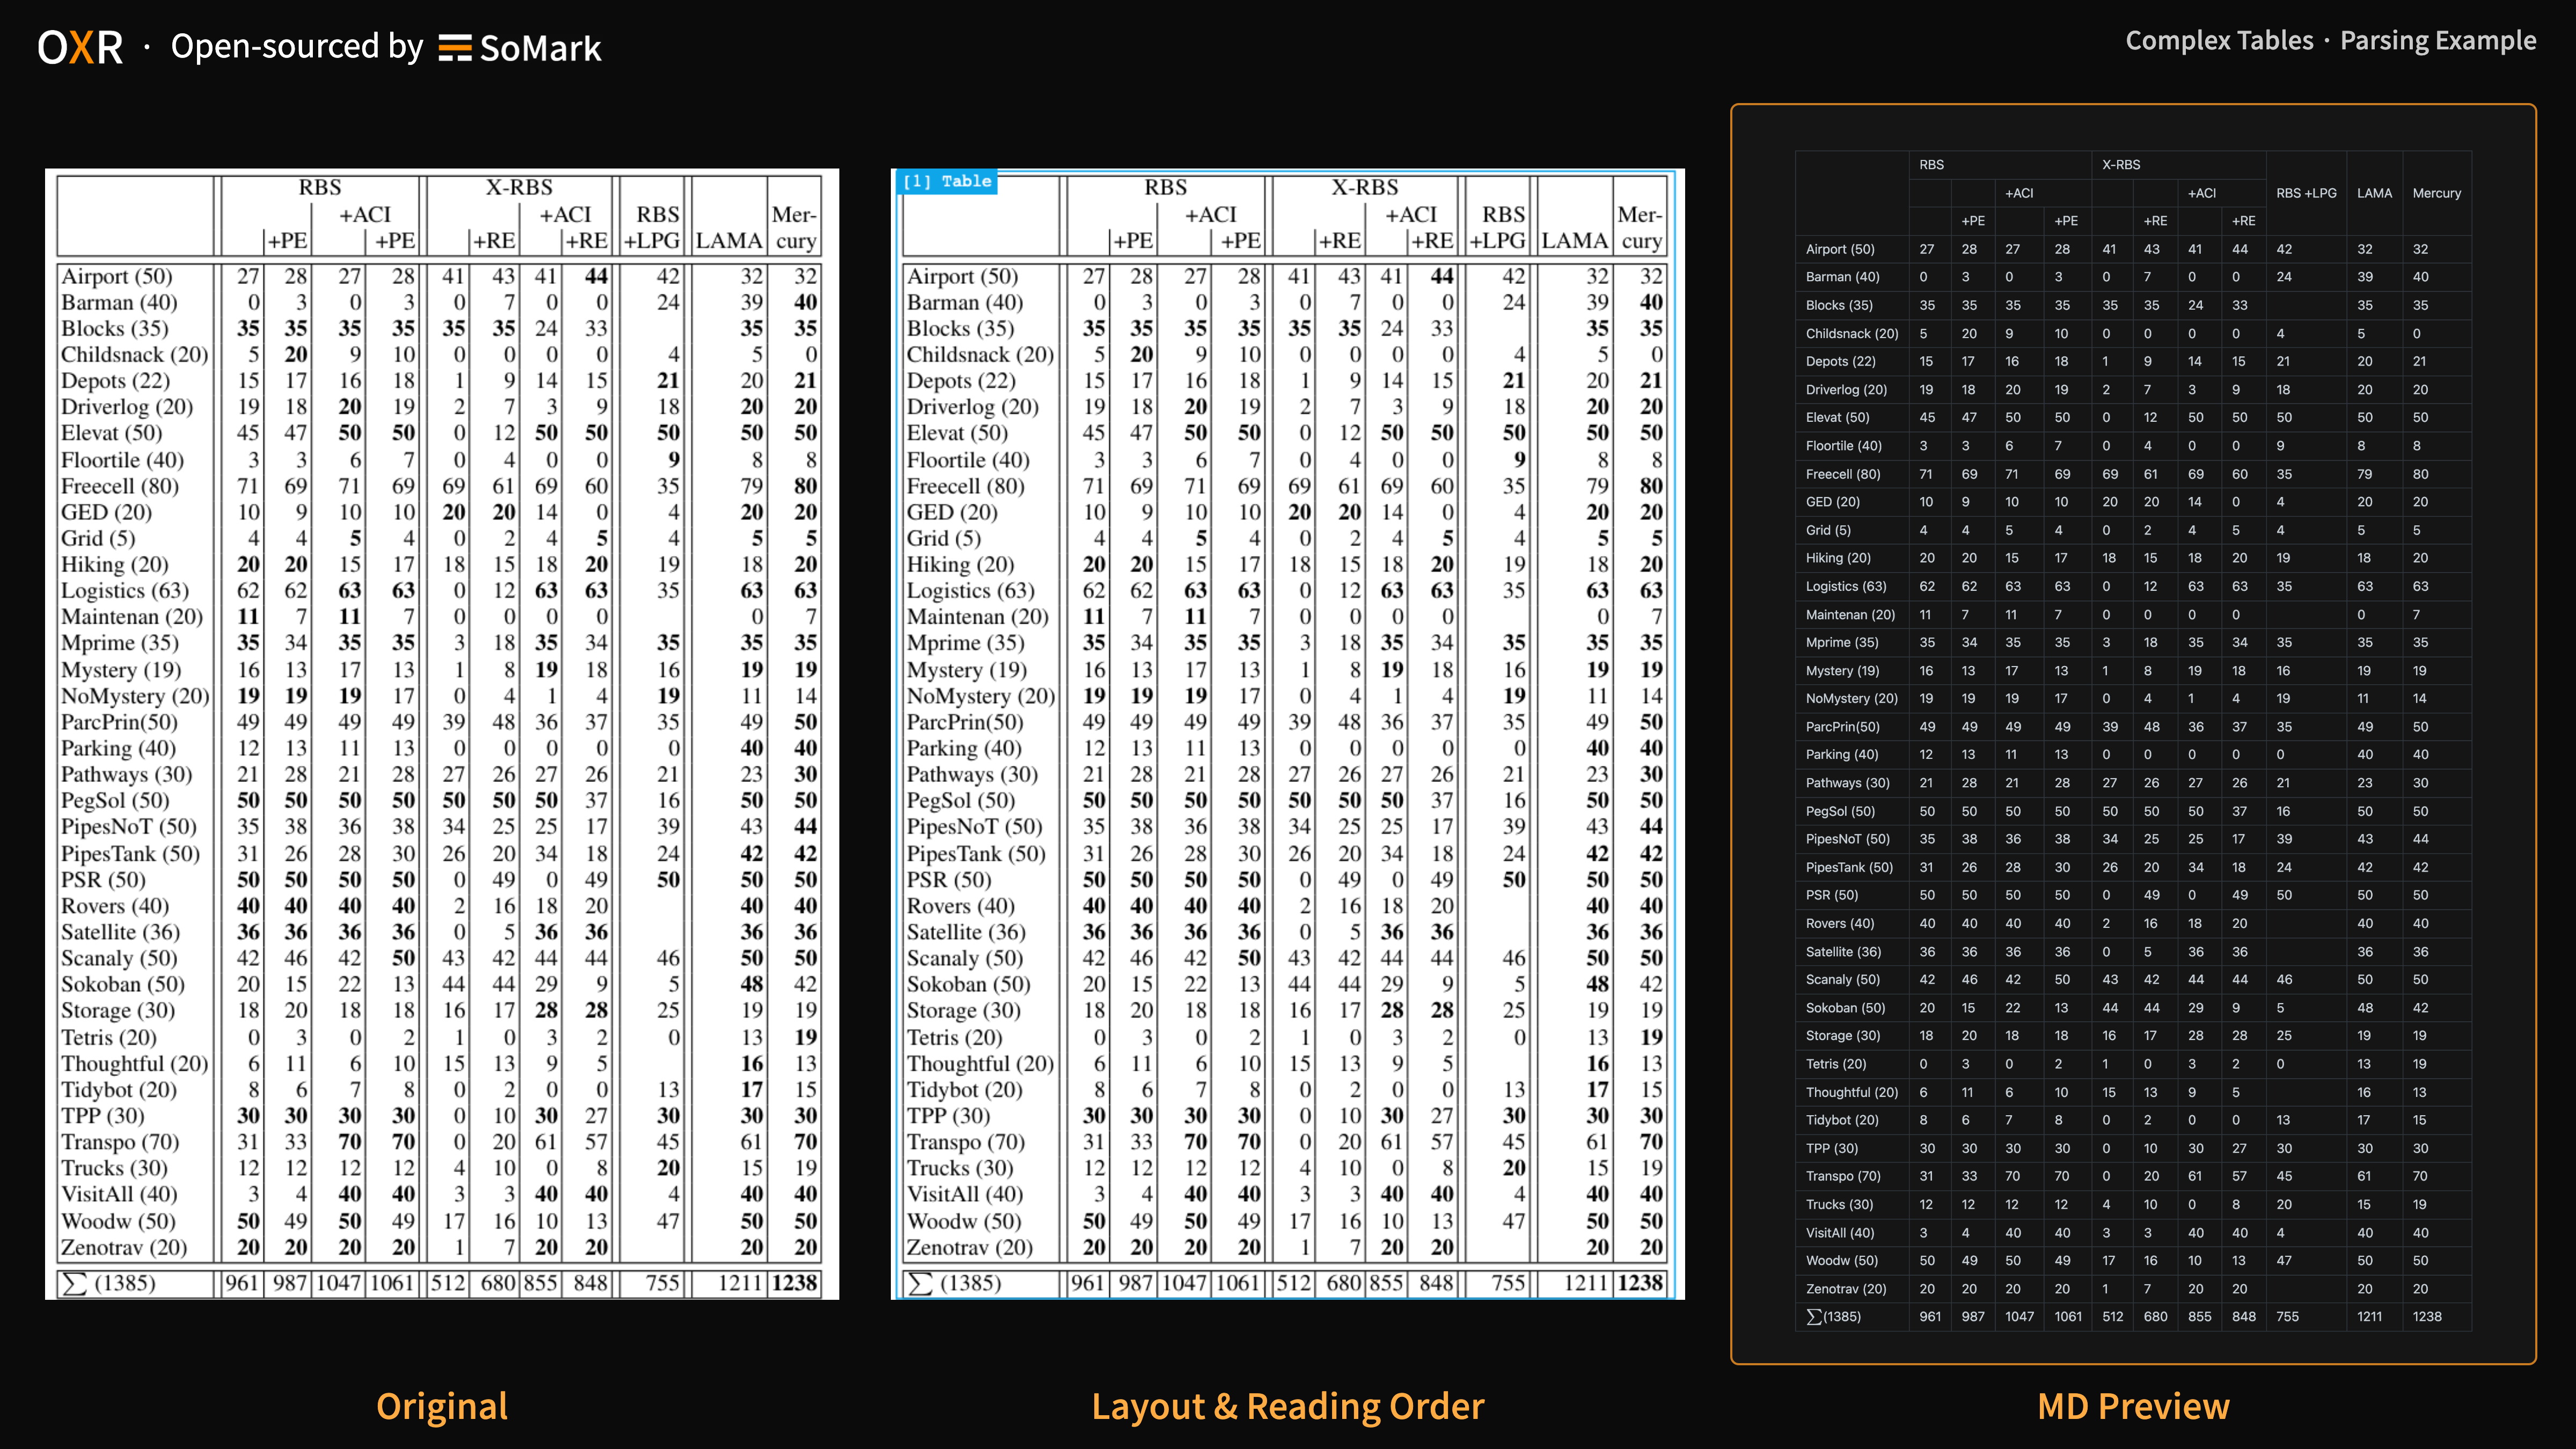 | Academic Paper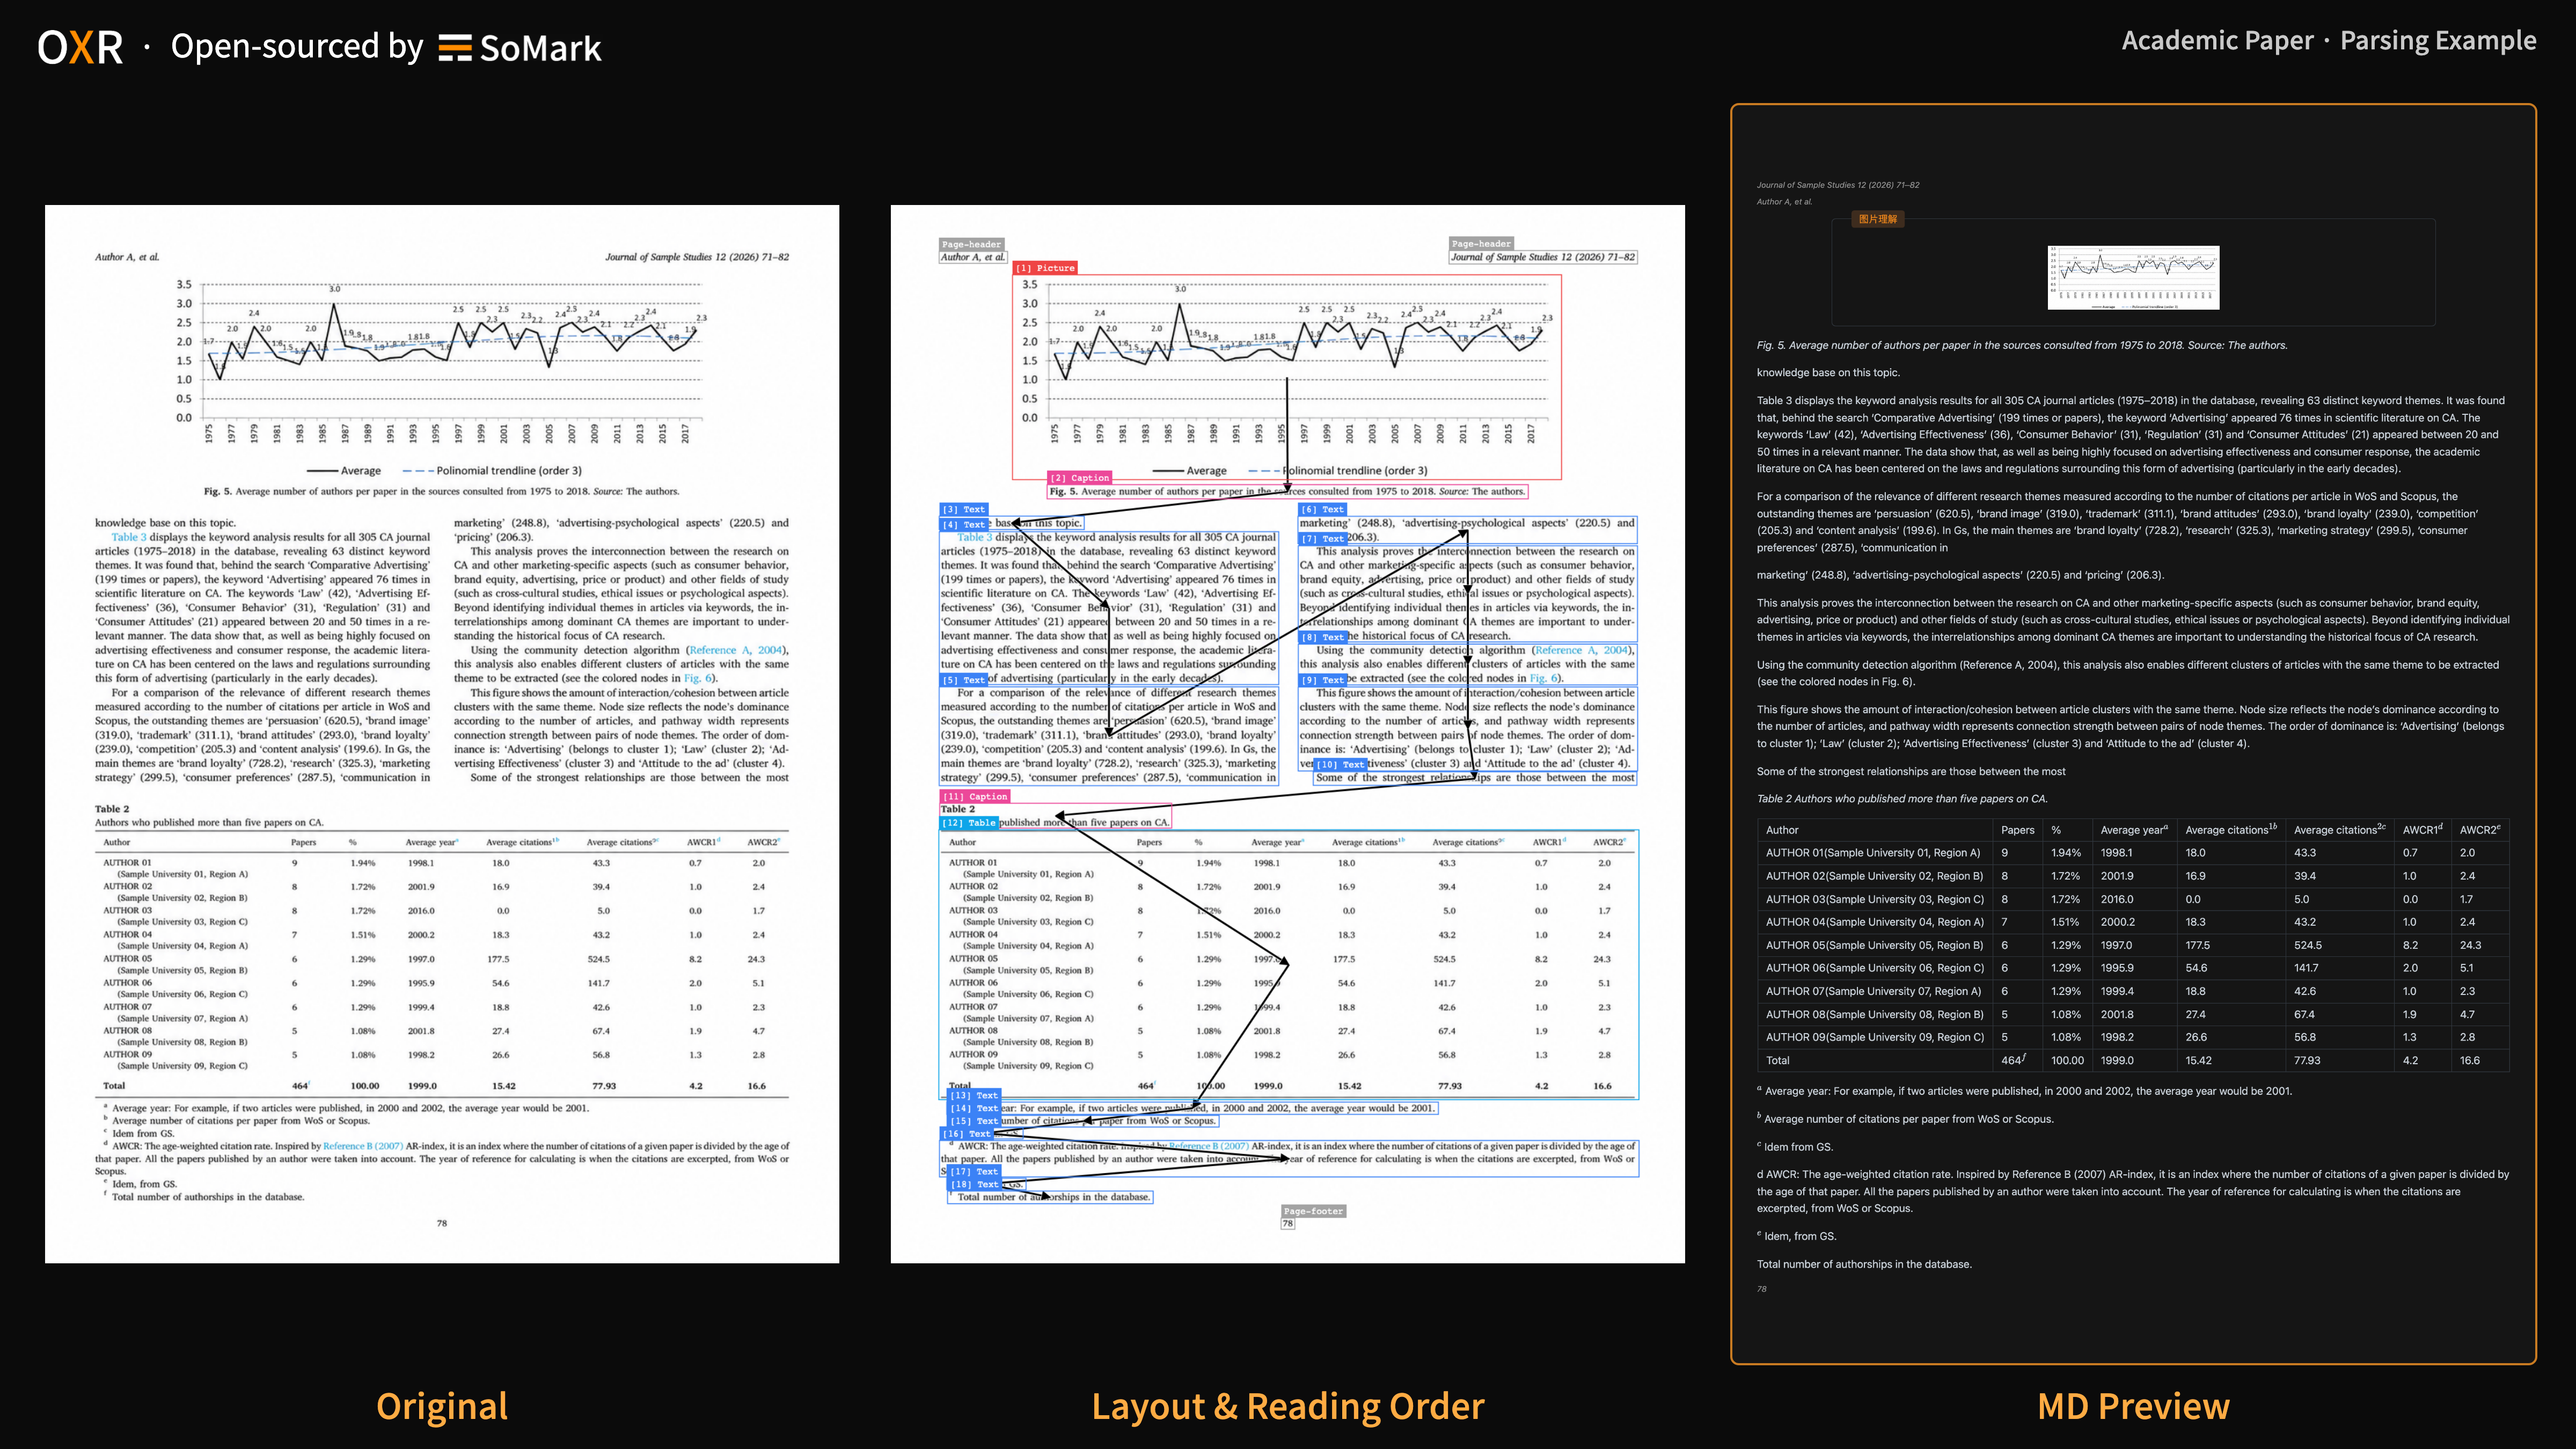 | Newspaper |
More in document-data-ai
microsoft / markitdown
A Python tool that converts files and Office documents to Markdown.
D4Vinci / Scrapling
A Python web-scraping framework for work ranging from individual requests to larger crawls, with browser and automation-oriented tooling.

bilawalsidhu / gods-eye-view
A browser-based spatial-intelligence interface that visualizes live open data on a photorealistic 3D globe.

ARahim3 / DigUp
A desktop app for on-device semantic search across photos, PDFs, documents, recordings and videos, built on EmbeddingGemma 2.